
Lesson 10: Convolution
Convolution is the core operation behind blurring, sharpening, and edge detection — and it's also the operation at the heart of a convolutional neural network's convolution layers (Lesson 34). This lesson builds it from scratch, clarifies a common point of confusion (convolution vs. correlation), and shows a few classic filters.
import numpy as np
import cv2
import matplotlib.pyplot as plt
1D convolution
Before tackling 2D images, let's first start with the simpler problem of convolving two 1D arrays. For a signal $I$ and a kernel $K$, the discrete convolution is
$$(I * K)(x) = \sum_{i} K(i)\, I(x - i)$$
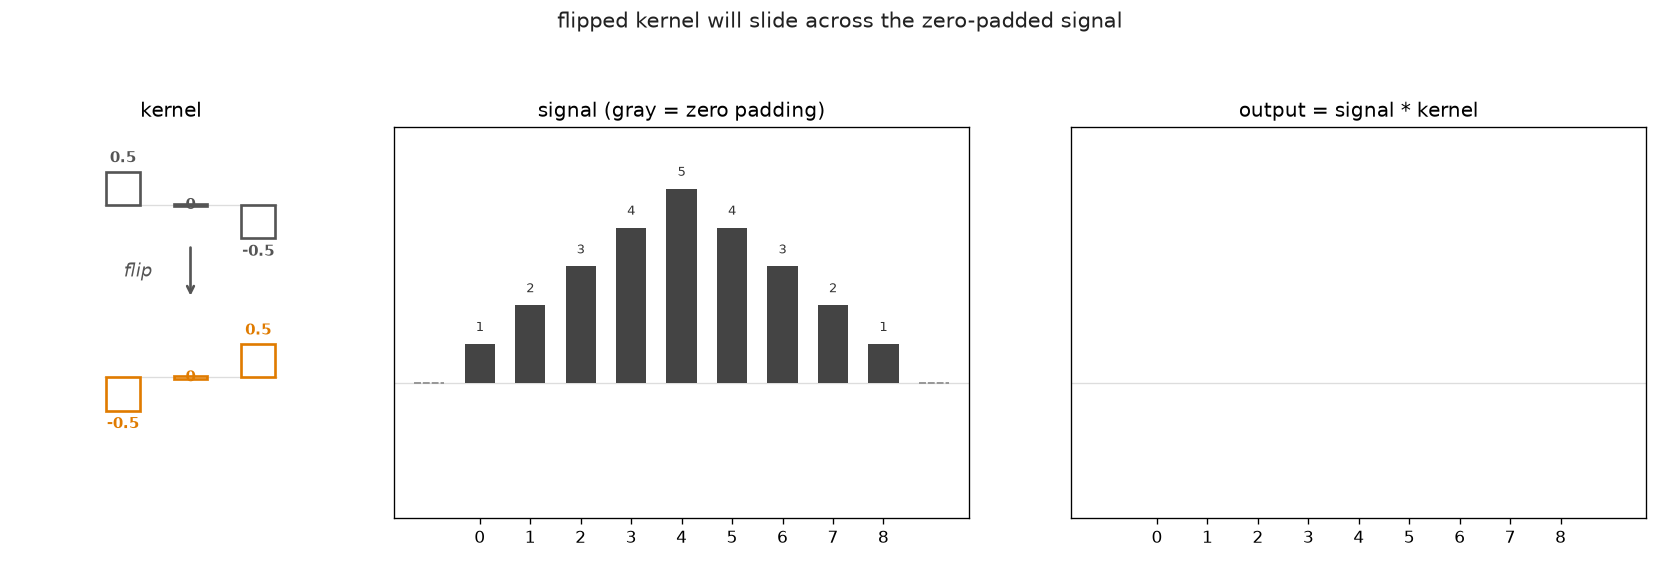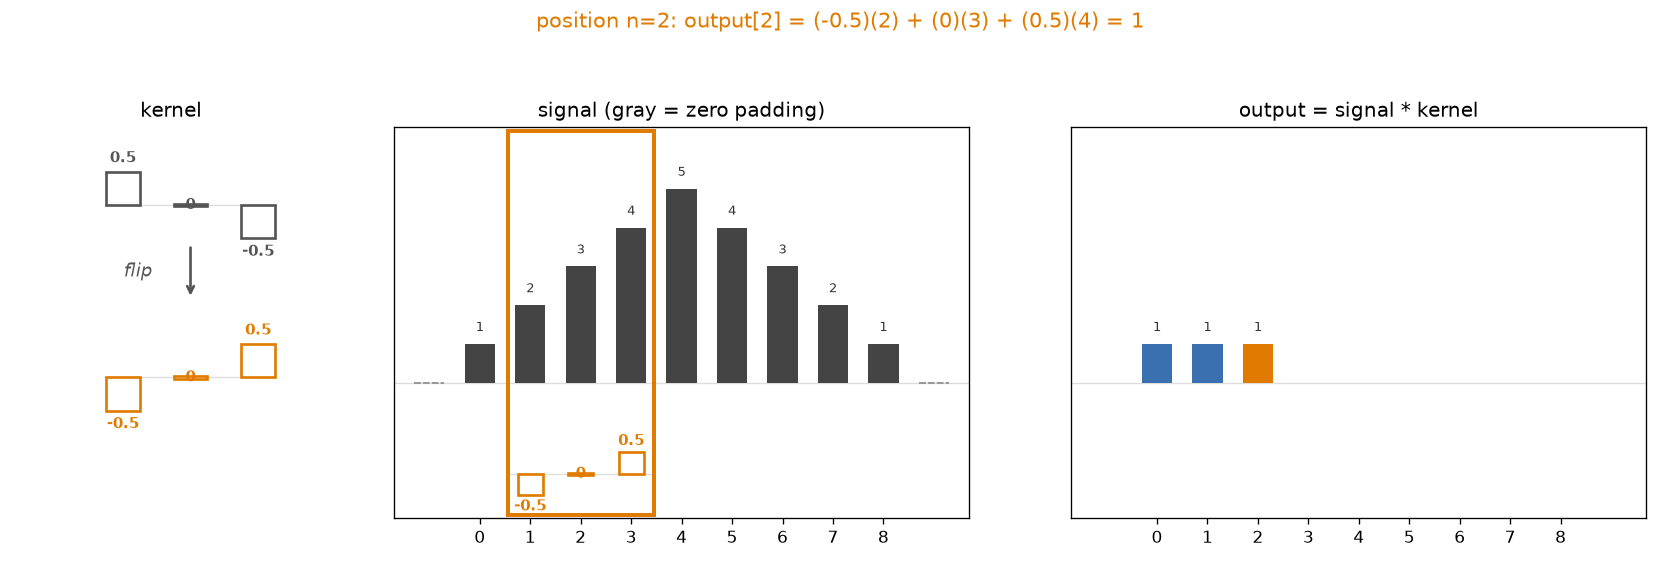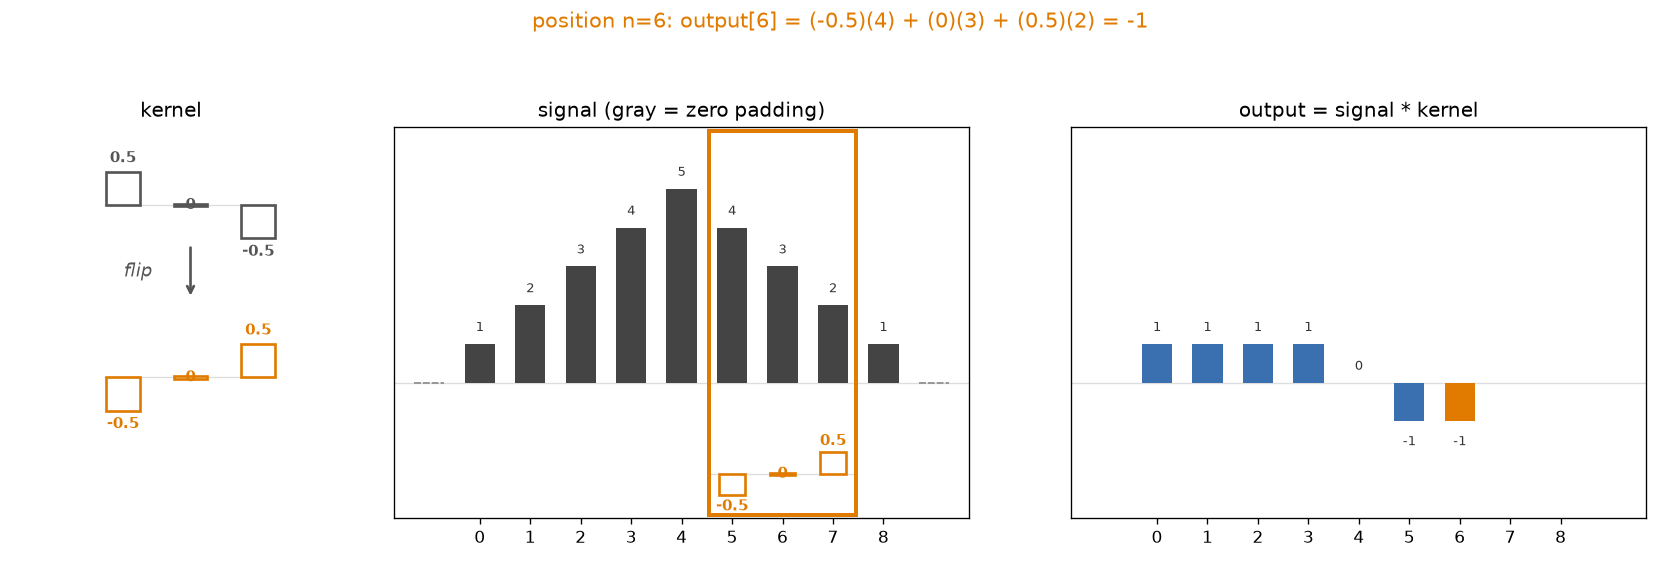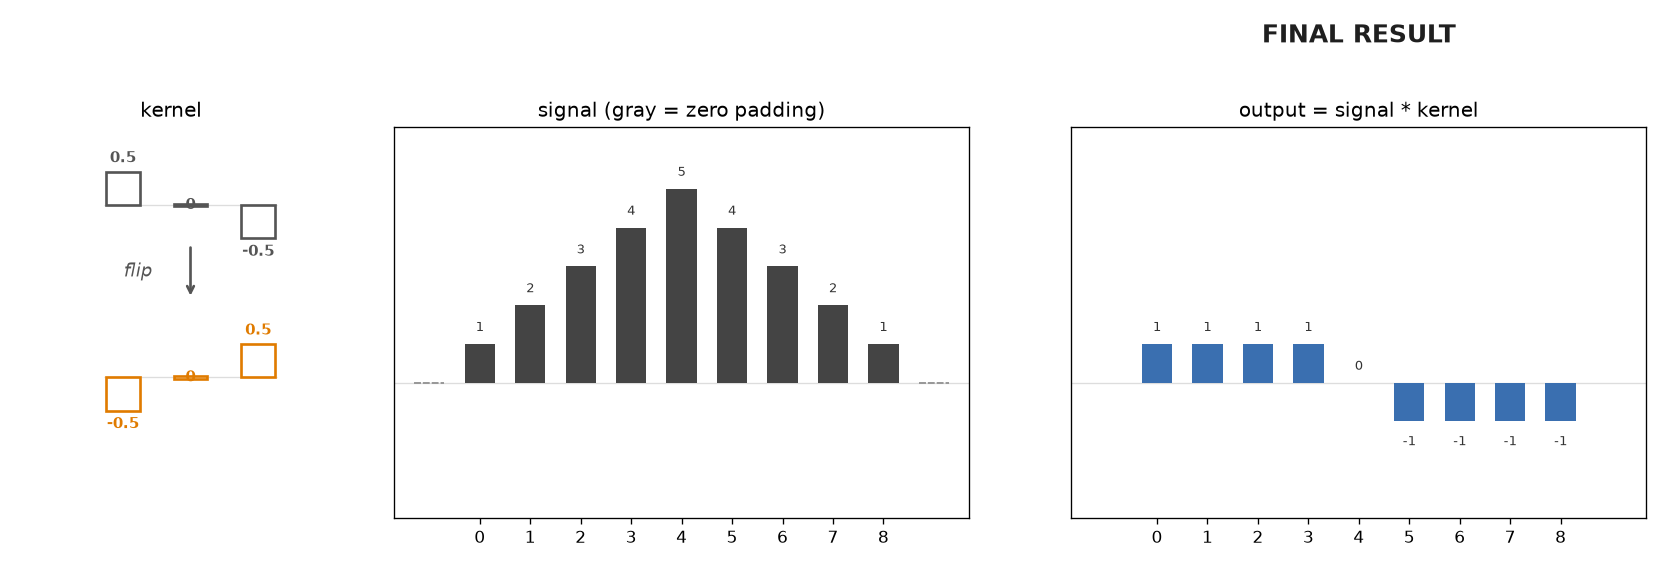
Concretely: flip the kernel end-to-end, slide it along the signal one position at a time, and at each position take the dot product between the flipped kernel and the overlapping chunk of signal. Now let's try it with a signal that ramps up and back down, and a simple 3-tap kernel $[-1, 0, 1]$ — a discrete derivative that calculates slope.
def convolve1d(signal, kernel):
    ksize = len(kernel)
    pad = ksize // 2
    padded = np.pad(signal, pad, mode='constant')
    flipped = kernel[::-1]
    out = np.zeros_like(signal, dtype=np.float64)
    for n in range(len(signal)):
        window = padded[n:n + ksize]
        out[n] = np.dot(window, flipped)
    return out

signal = np.array([1, 2, 3, 4, 5, 4, 3, 2, 1], dtype=np.float64)
kernel = 0.5 * np.array([1, 0, -1], dtype=np.float64) # pre-flipped; scaling factor ensures that result is slope

mine = convolve1d(signal, kernel)
reference = np.convolve(signal, kernel, mode='same')
print('signal:   ', signal)
print('mine:     ', mine)
print('np.convolve:', reference)
print('match:', np.allclose(mine, reference))

fig, axes = plt.subplots(1, 2, figsize=(8, 3))
axes[0].plot(signal, marker='o')
axes[0].set_title('Signal')
axes[1].plot(mine, marker='o', color='tab:orange')
axes[1].axhline(0, color='gray', linewidth=0.8)
axes[1].set_title('Signal * [1, 0, -1]')
plt.tight_layout()
plt.show()

Note the output is positive while the signal is rising, zero at the peak, and negative while it's falling — exactly what a derivative-like kernel should do.
Here's the same computation animated step by step: the kernel is first flipped, then the flipped kernel slides across the zero-padded signal one position at a time, taking a dot product at each step to produce one output value.
2D convolution
The 2D version of convolution (what actually gets used on images) is the same flip-and-slide idea as the 1D case above, just over two axes:
$$(I * K)(x, y) = \sum_{i}\sum_{j} K(i, j)\, I(x - i,\, y - j)$$
with image $I$ and kernel $K$. Just as with the 1D version, the key detail is the minus signs: the kernel is flipped (rotated 180°) before it's slid across the image. This matters whenever the kernel is not symmetric.
Correlation is the same idea without the flip:
$$(I \star K)(x, y) = \sum_{i}\sum_{j} K(i, j)\, I(x + i,\, y + j)$$
In practice, most image-processing libraries — including OpenCV's cv2.filter2D — actually implement correlation, not convolution, even though people casually call it "convolving with a kernel." For symmetric kernels (box blur, Gaussian) the two are identical, so the distinction rarely matters in practice. But it's worth knowing the difference exists.
Convolution from scratch
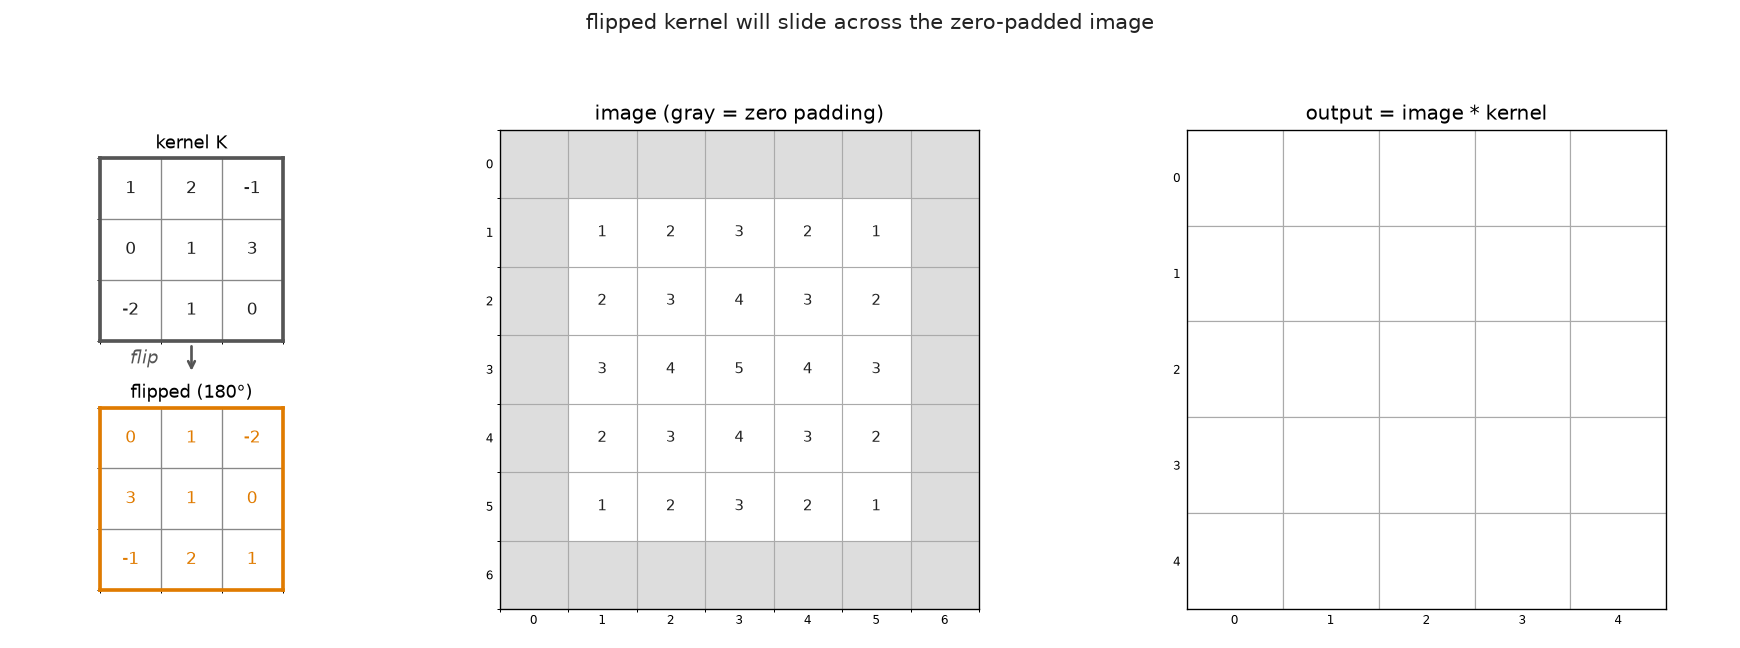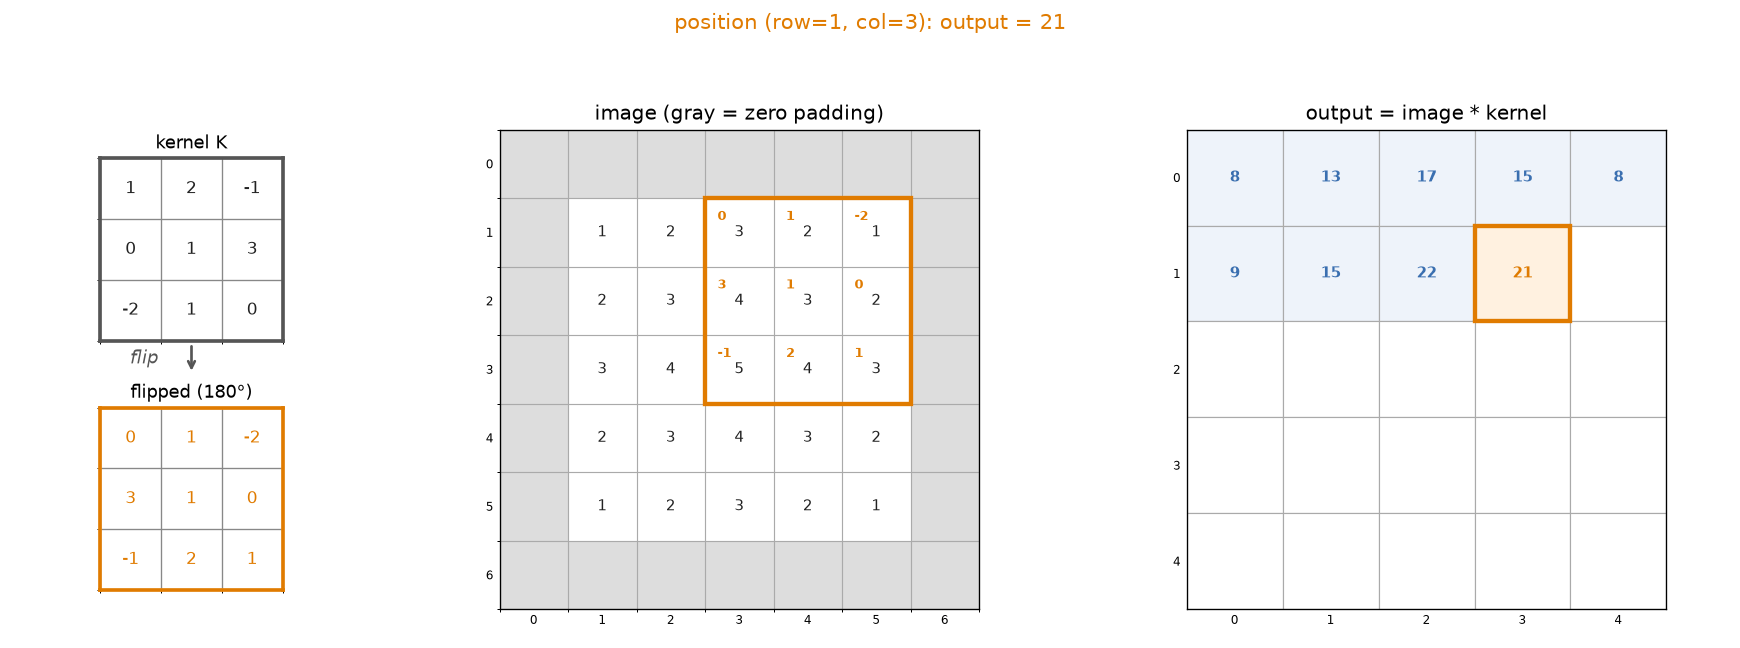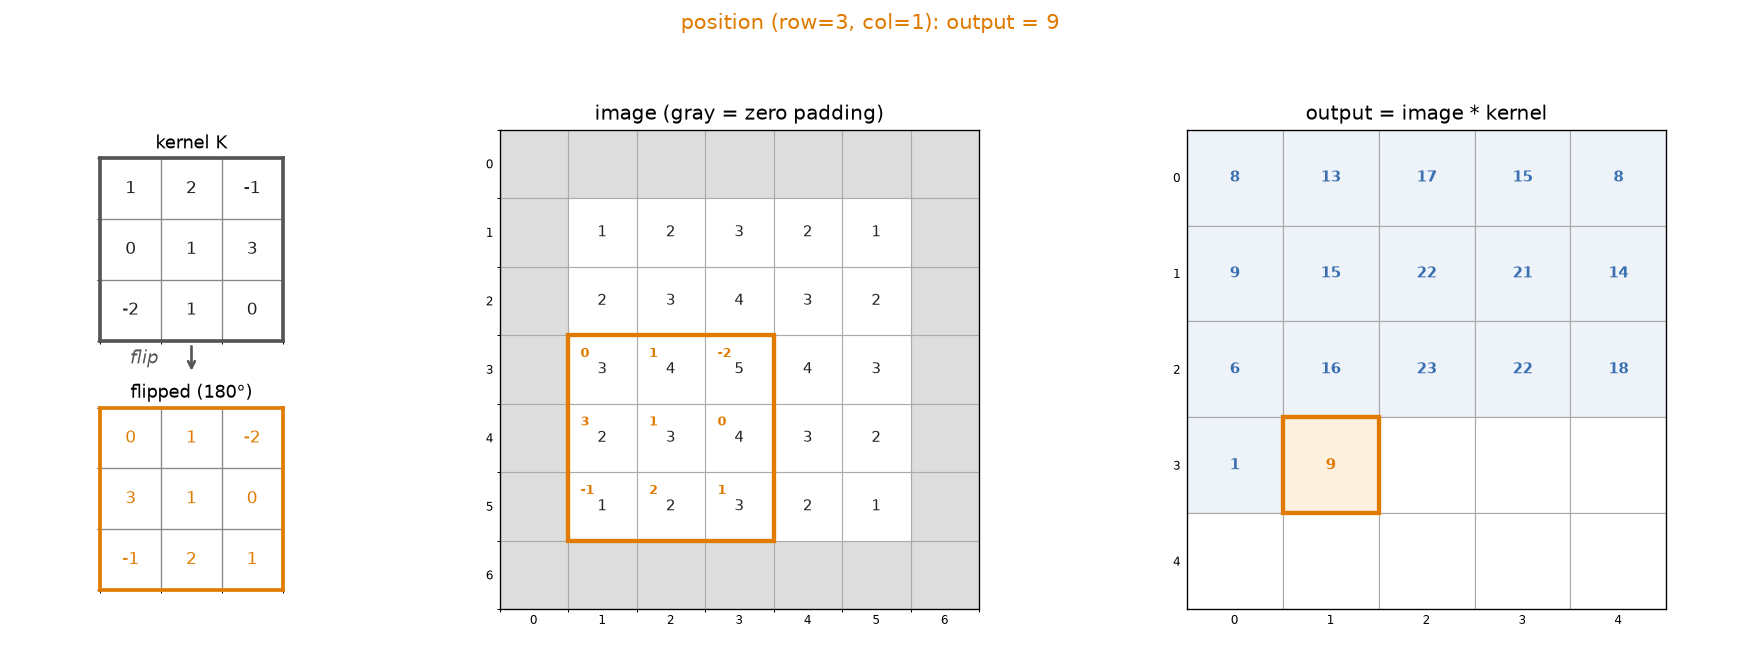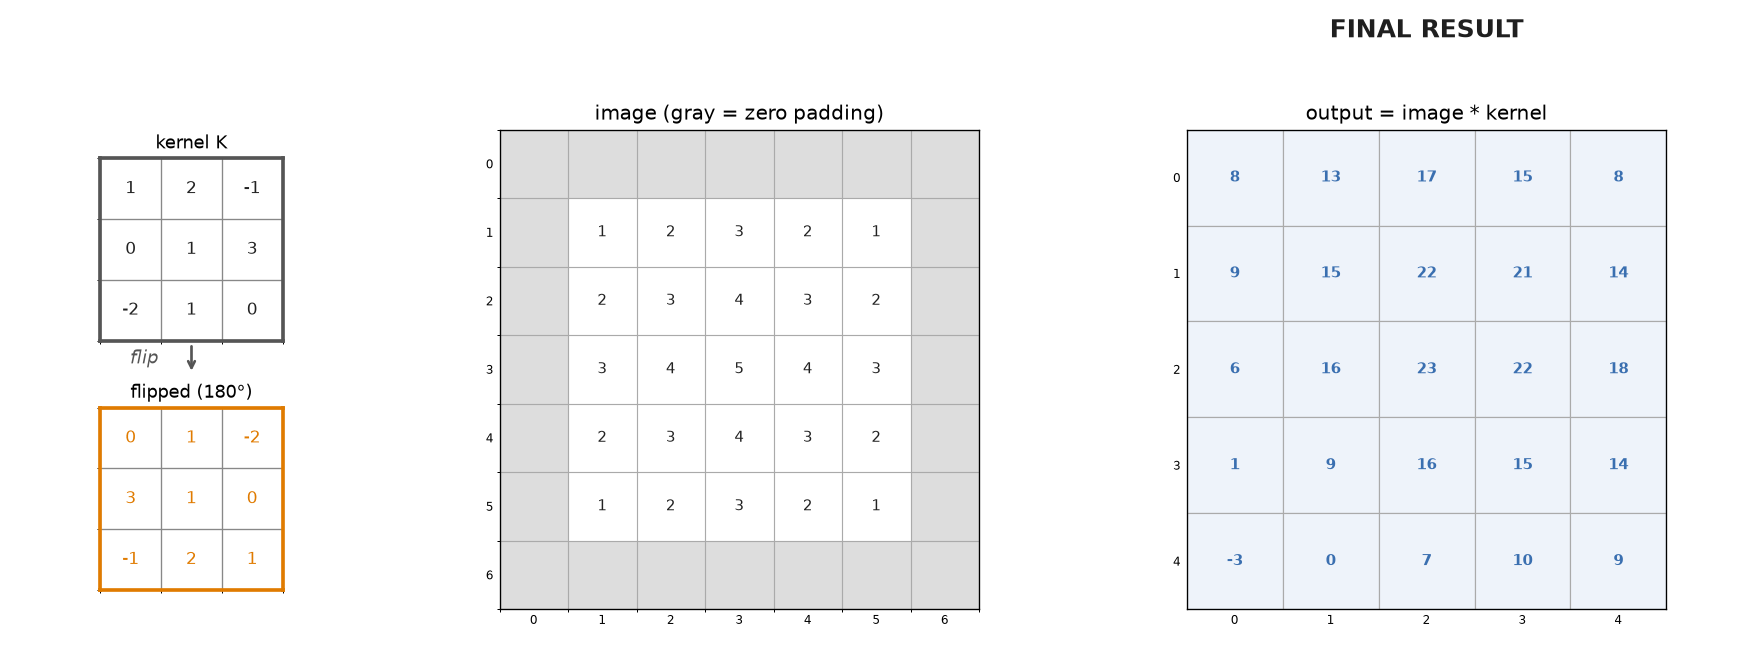
To implement 2D convolution: flip the kernel both horizontally and vertically, pad the image so the kernel never runs off the edge, then at every position multiply the flipped kernel elementwise by the pixels underneath it and sum.
Shown in this animation: flip the kernel 180°, then slide it across a small zero-padded image, taking a dot product with the overlapping 3x3 window at each position. This is the same asymmetric kernel used again below in the convolution-vs-correlation comparison, where the flip will visibly matter.
Speeding up convolution: loop over the kernel, not the image
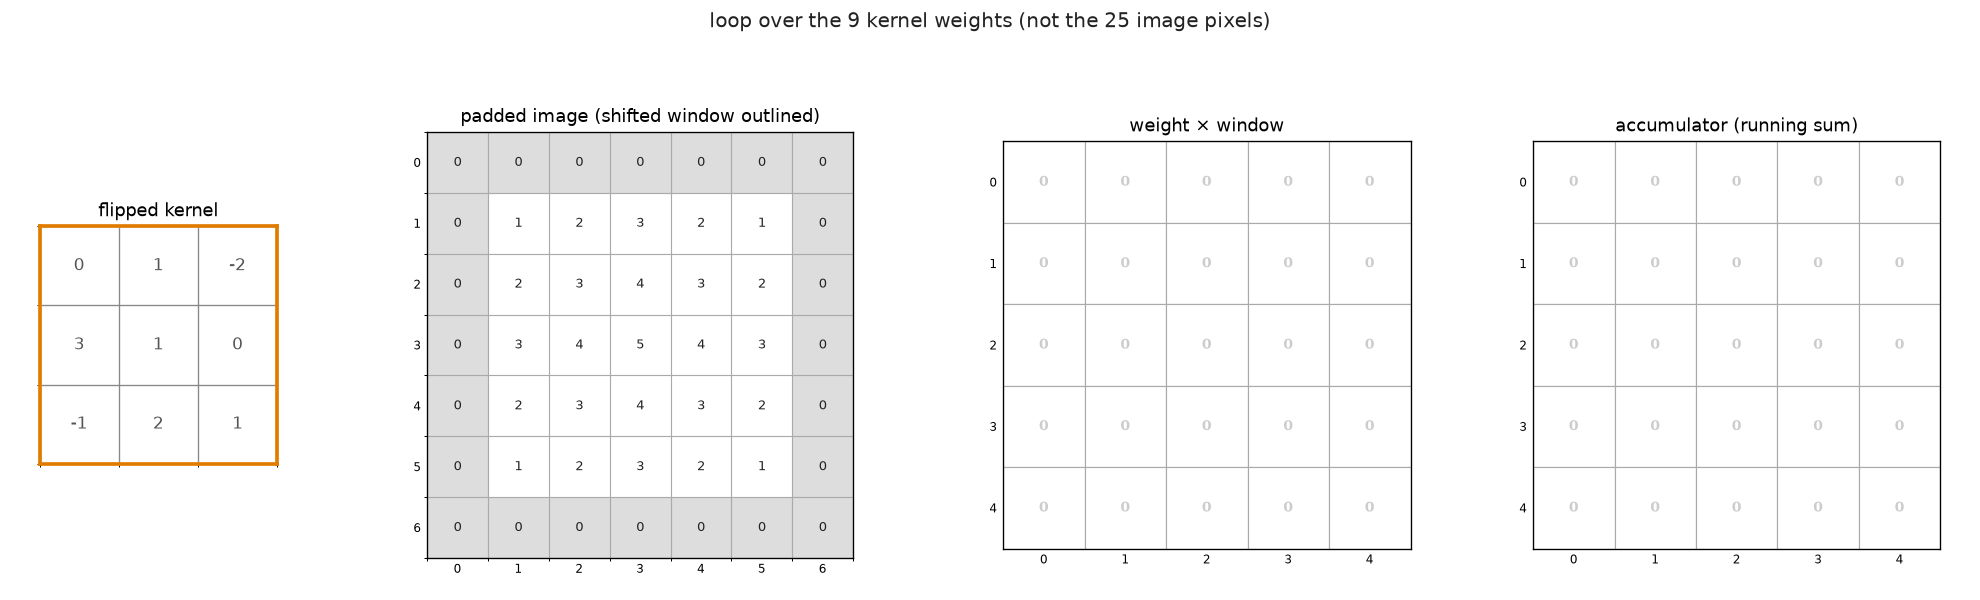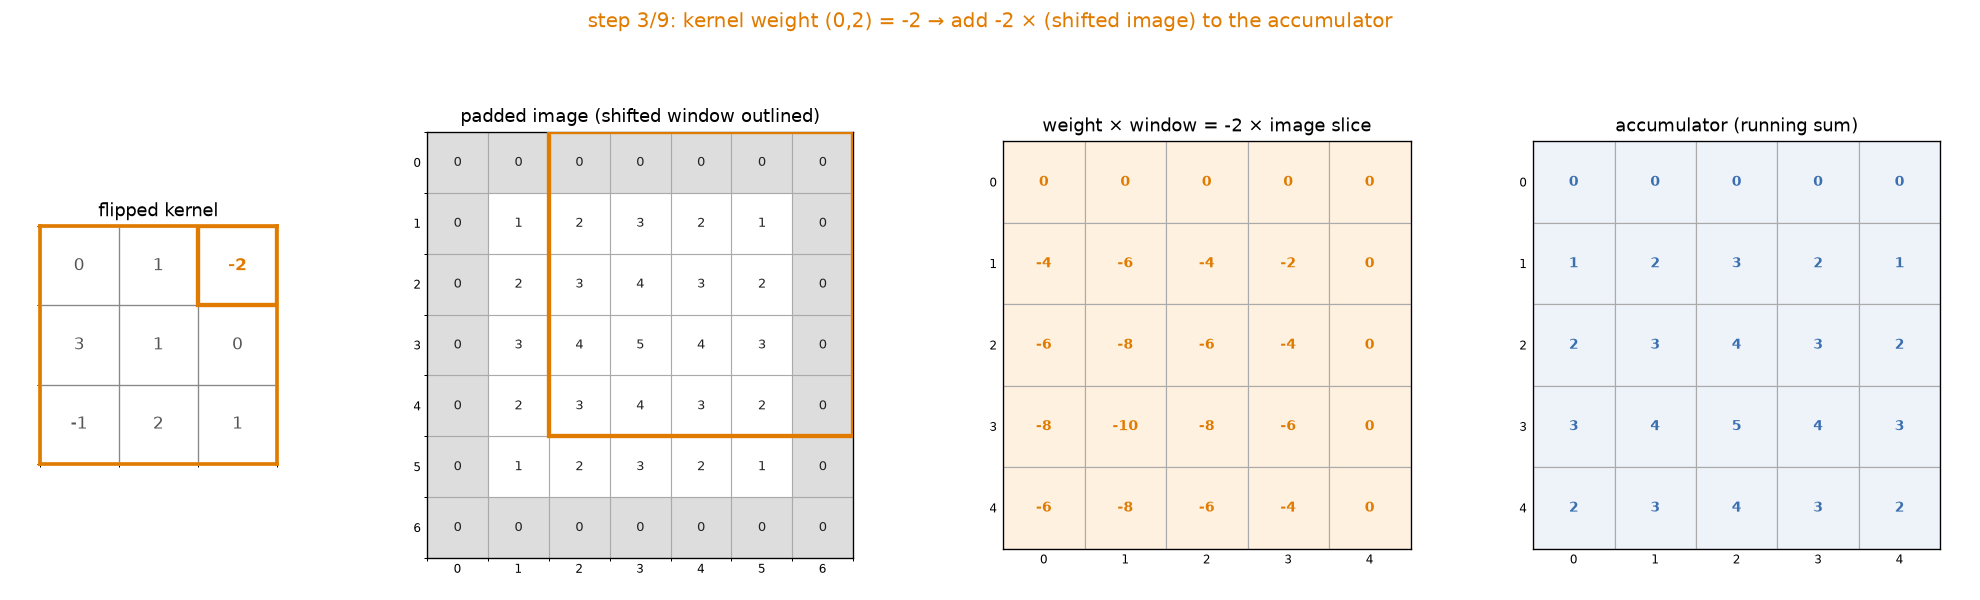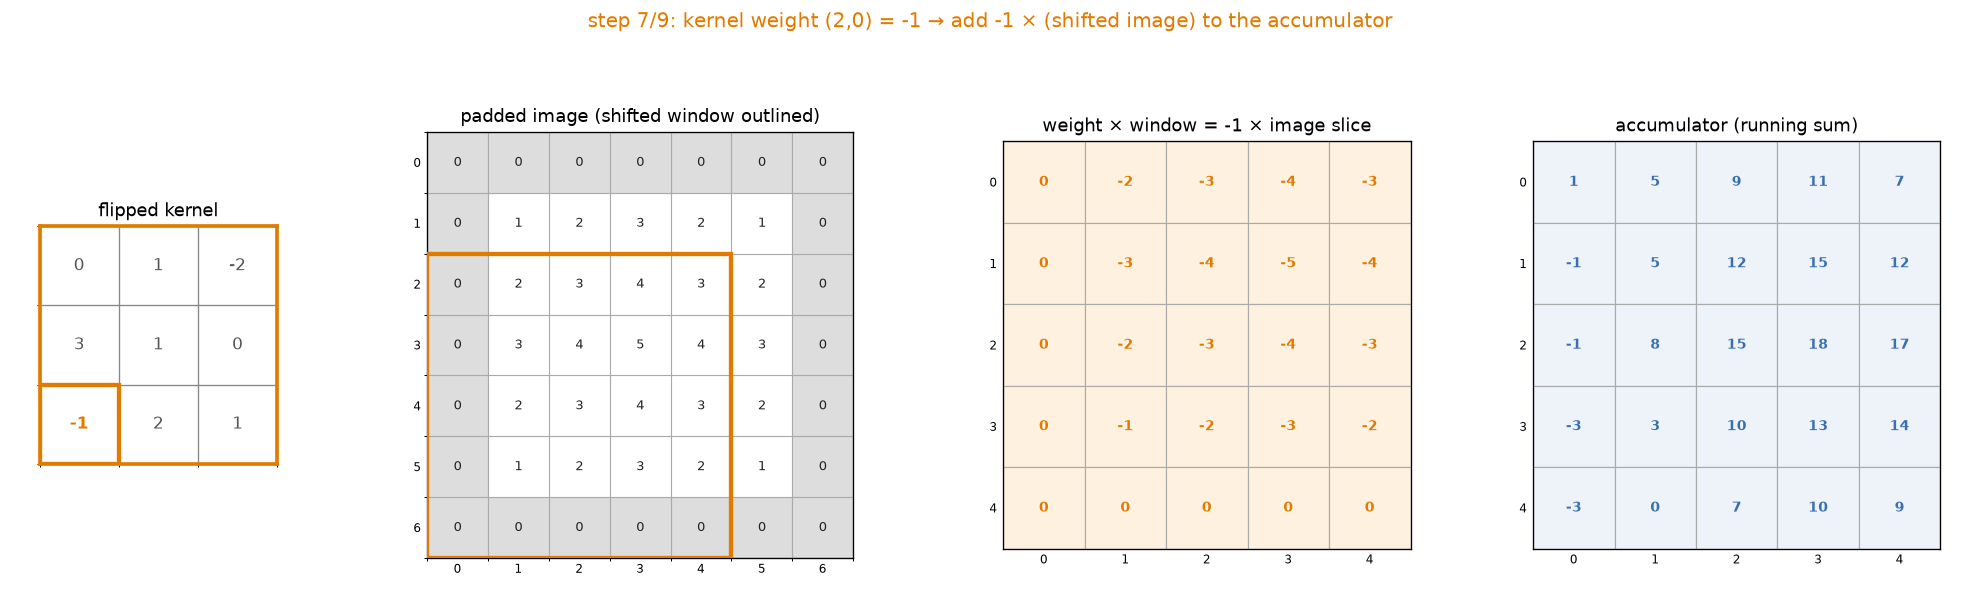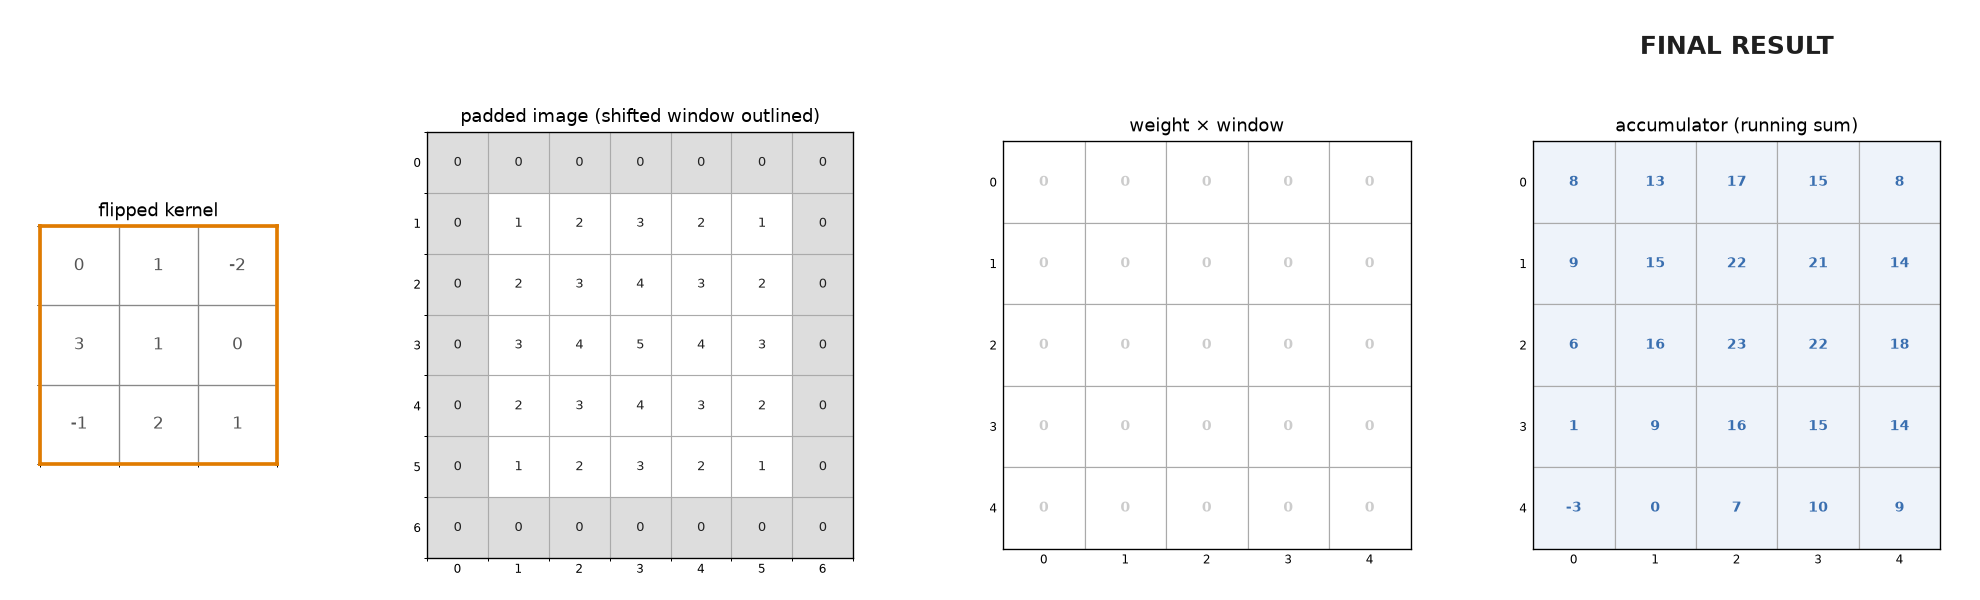
The code below implements 2D convolution directly — except that for speed it loops over the kernel's (few) entries rather than the image's (many) pixels, shifting and accumulating the whole padded image at once for each kernel weight.
def convolve2d(image, kernel, border=cv2.BORDER_REFLECT101):
    """True convolution (kernel is flipped), single-channel, float output."""
    kh, kw = kernel.shape
    pad_h, pad_w = kh // 2, kw // 2
    flipped = kernel[::-1, ::-1]
    padded = cv2.copyMakeBorder(image, pad_h, pad_h, pad_w, pad_w, border)

    out = np.zeros(image.shape, dtype=np.float64)
    for i in range(kh):  # loop over kernel values for speed (kernel is smaller than image)
        for j in range(kw):
            out += flipped[i, j] * padded[i:i + image.shape[0], j:j + image.shape[1]].astype(np.float64)
    return out
Here's the trick animated, on the same image and kernel as above: instead of lighting up one output cell per step, each step now lights up one kernel weight and adds a shifted, scaled copy of the entire image to a running accumulator — so after only 9 steps (one per kernel weight) rather than 25 (one per pixel), the accumulator achieves the same result.
Sanity check against OpenCV
Since cv2.filter2D computes correlation, we feed it the pre-flipped kernel to get a true convolution result to compare against.
test_img = np.zeros((20, 20), dtype=np.uint8)
test_img[3:17, 3:6] = 200   # a small "corner" shape (no symmetry), so flipping is visible
test_img[3:6, 3:14] = 200

asymmetric_kernel = np.array([[1, 2, -1],
                               [0, 1,  3],
                               [-2, 1, 0]], dtype=np.float64)

mine = convolve2d(test_img, asymmetric_kernel)
reference = cv2.filter2D(test_img, cv2.CV_64F, asymmetric_kernel[::-1, ::-1],
                          borderType=cv2.BORDER_REFLECT101)

print('max abs difference:', np.abs(mine - reference).max())
Convolution vs. correlation, made visible
For a symmetric kernel, convolving and correlating give identical results. For an asymmetric kernel, the results are different — but most asymmetric kernels in practice cause a simple sign flip.
correlated = cv2.filter2D(test_img, cv2.CV_64F, asymmetric_kernel, borderType=cv2.BORDER_REFLECT101)

fig, axes = plt.subplots(1, 3, figsize=(9, 3.5))
for ax, im, title in zip(axes, [test_img, mine, correlated],
                          ['Original', 'Convolution\n(kernel flipped)', 'Correlation\n(kernel not flipped)']):
    ax.imshow(im, cmap='gray')
    ax.set_title(title, fontsize=9)
    ax.axis('off')
plt.tight_layout()
plt.show()

print('convolution == correlation with kernel rotated 180?',
      np.allclose(mine, cv2.filter2D(test_img, cv2.CV_64F, asymmetric_kernel[::-1, ::-1],
                                      borderType=cv2.BORDER_REFLECT101)))

Boundary handling
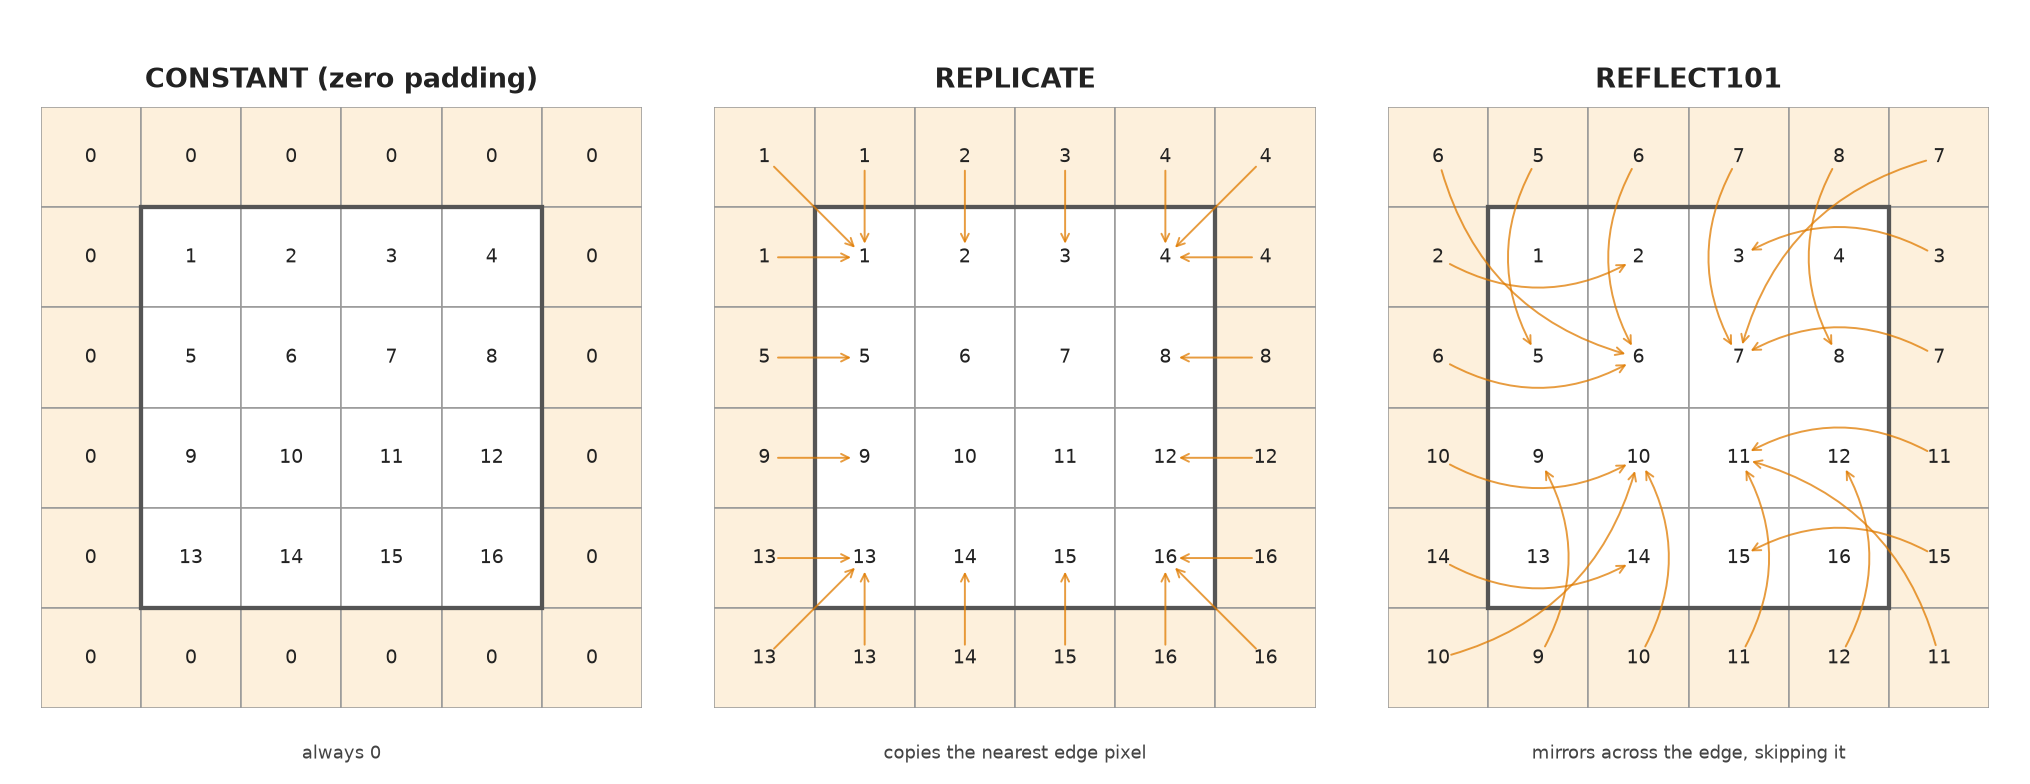
Near the edges, the kernel hangs off the image. convolve2d uses cv2.copyMakeBorder to pad first; the padding mode changes the result at the border. Common choices: constant (zero) padding, replicate (extend the edge pixel), and reflect (mirror across the edge). For the latter, there are two choices: REFLECT101 is more common as it avoids duplicating the edge pixel itself. In this example, the inner $4 \times 4$ array of each output is identical to the original array — only the outer ring is different.
small = np.arange(1, 17, dtype=np.float64).reshape(4, 4)

for name, mode in [('CONSTANT (zero)', cv2.BORDER_CONSTANT),
                    ('REPLICATE', cv2.BORDER_REPLICATE),
                    ('REFLECT101', cv2.BORDER_REFLECT101)]:
    padded = cv2.copyMakeBorder(small, 1, 1, 1, 1, mode)
    print(f'{name}:\n{padded}\n')
Here's the same three modes compared side by side, with an arrow from each padding cell back to the interior pixel its value comes from (CONSTANT has no arrows, since every padding cell is simply 0):
Classic filters as kernels
Once we can convolve, most filters are just "pick a kernel":
- Box blur: every neighbor weighted equally — averages out noise but blurs edges.
- Blur (separable): neighbors weighted more heavily toward the center (tent-shaped) — smoother falloff than a box blur, and, as we'll see below, it can be built from two 1D kernels.
- Sharpen: boosts the center pixel relative to its neighbors.
- Sobel (edge detection): an asymmetric kernel that responds strongly to intensity changes in one direction — this is a case where the convolution-vs-correlation flip actually matters, since the kernel is asymmetric (results in a sign flip).
photo_like = np.zeros((100, 100), dtype=np.uint8)
cv2.rectangle(photo_like, (20, 20), (80, 80), 200, -1)
cv2.circle(photo_like, (50, 50), 20, 60, -1)
rng = np.random.default_rng(0)
photo_like = photo_like.astype(np.float64) + rng.normal(0, 12, photo_like.shape)
photo_like = np.clip(photo_like, 0, 255)

box = np.ones((5, 5)) / 25

k1d_int = np.array([1, 4, 6, 4, 1])  # binomial approximation to a Gaussian (Pascal's triangle, row 4)
k1d = k1d_int / k1d_int.sum()
gaussian = np.outer(k1d, k1d)

sharpen = np.array([[0, -1, 0],
                     [-1, 5, -1],
                     [0, -1, 0]], dtype=np.float64)

sobel_x = np.array([[-1, 0, 1],
                     [-2, 0, 2],
                     [-1, 0, 1]], dtype=np.float64)

results = {
    'Original (noisy)': photo_like,
    'Box blur': convolve2d(photo_like, box),
    'Blur (separable)': convolve2d(photo_like, gaussian),
    'Sharpen': convolve2d(photo_like, sharpen),
    'Sobel x (edges)': convolve2d(photo_like, sobel_x),
}

fig, axes = plt.subplots(1, 5, figsize=(15, 3.5))
for ax, (title, im) in zip(axes, results.items()):
    ax.imshow(im, cmap='gray')
    ax.set_title(title, fontsize=9)
    ax.axis('off')
plt.tight_layout()
plt.show()

Separable kernels: a speed trick
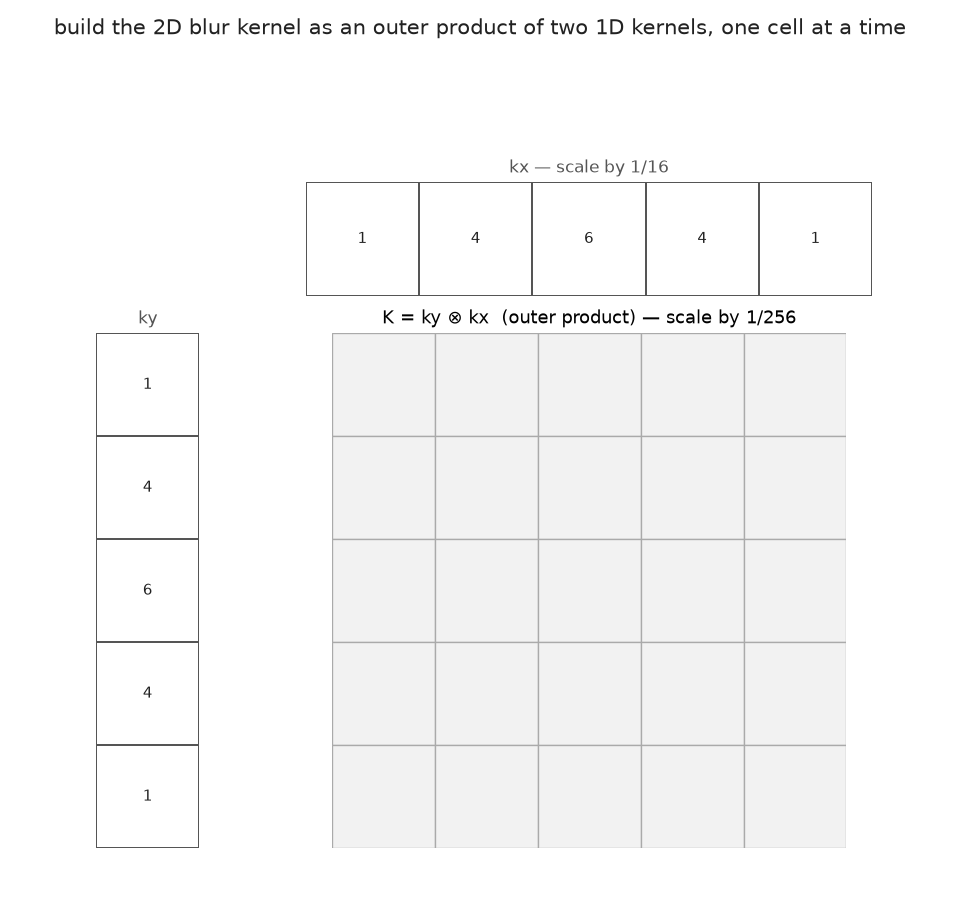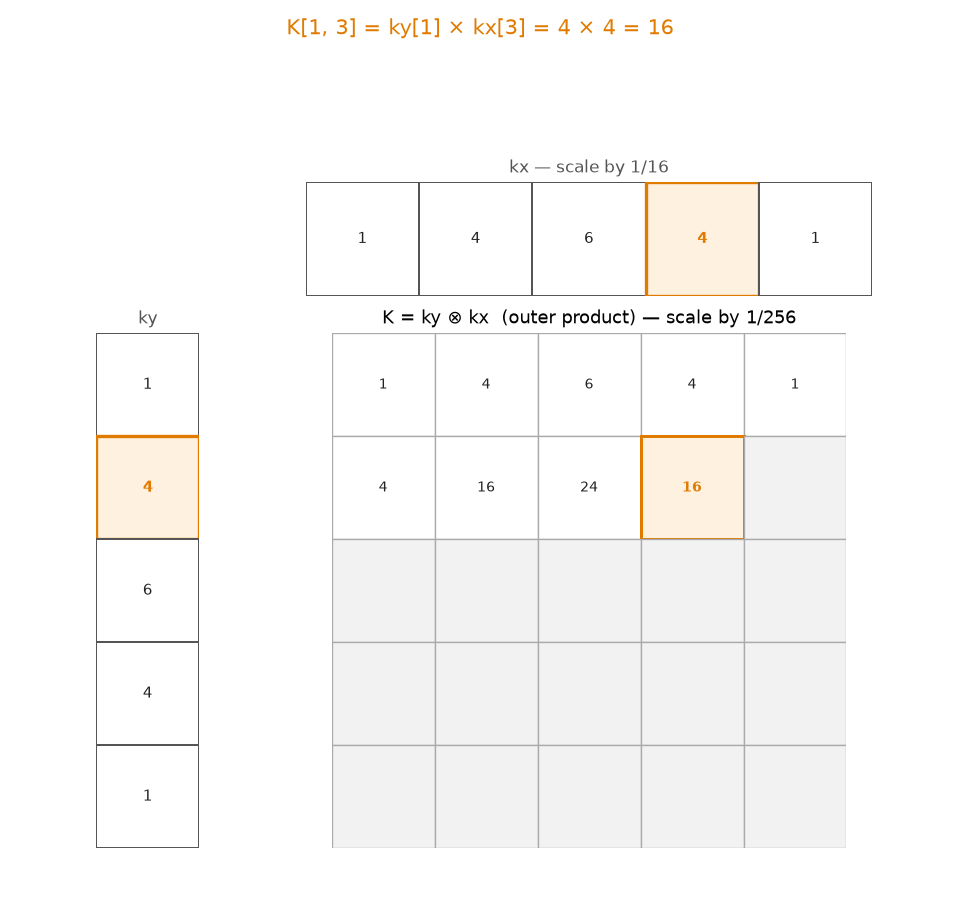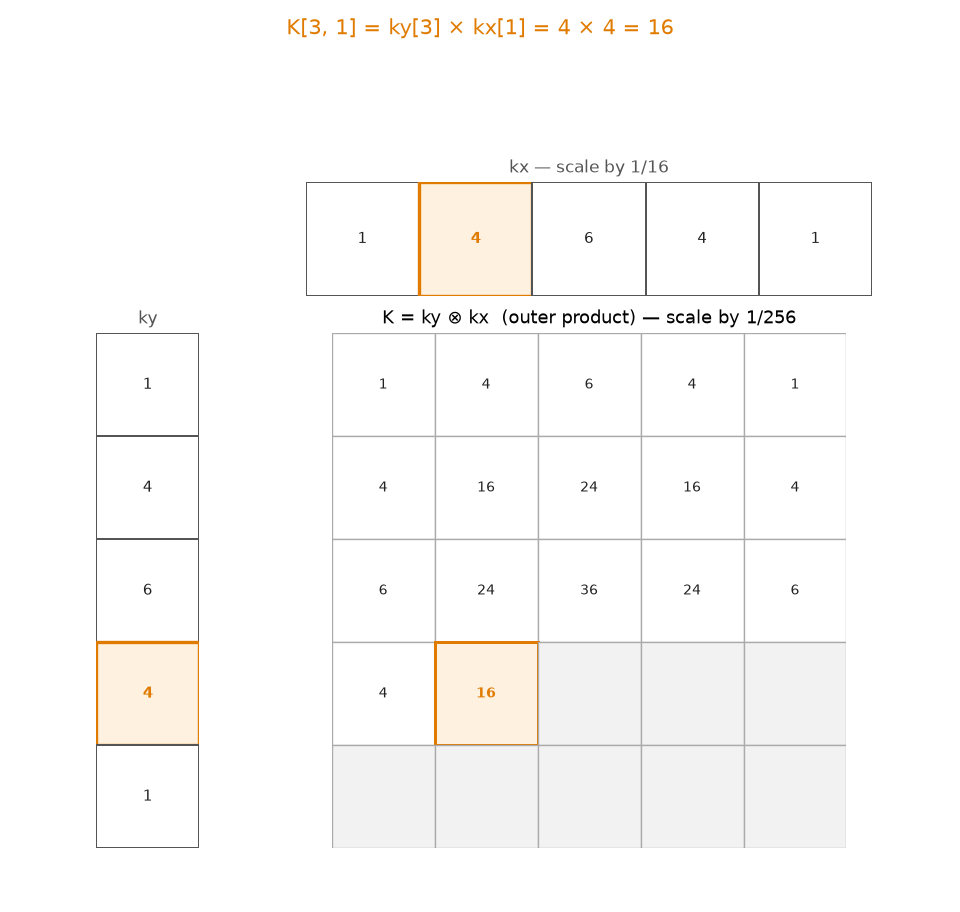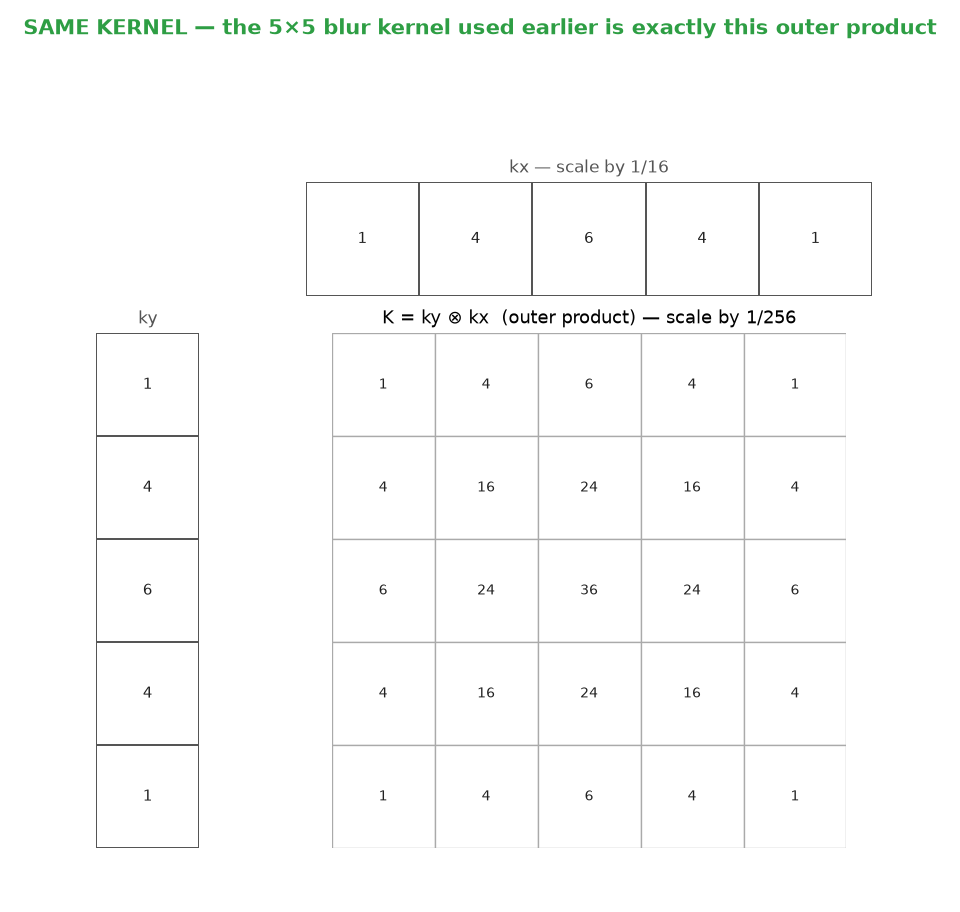
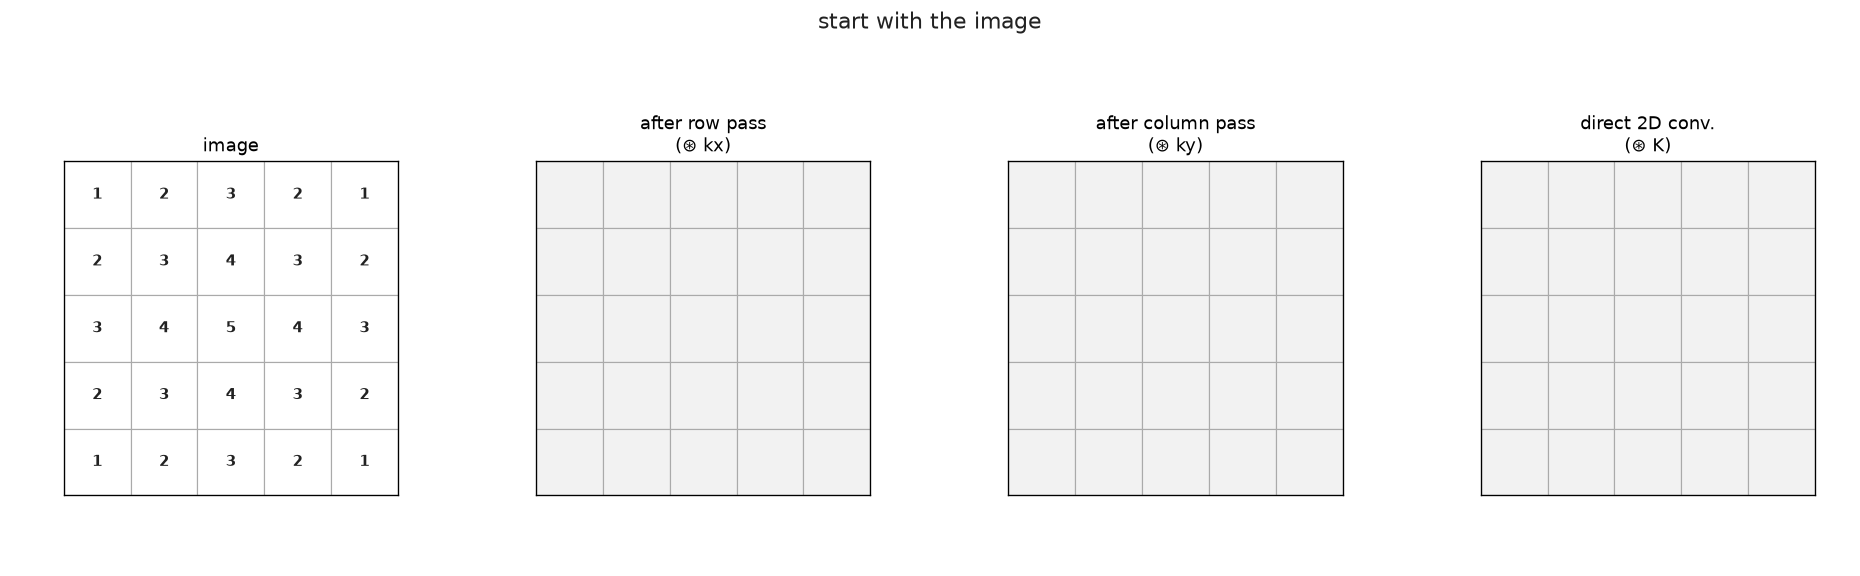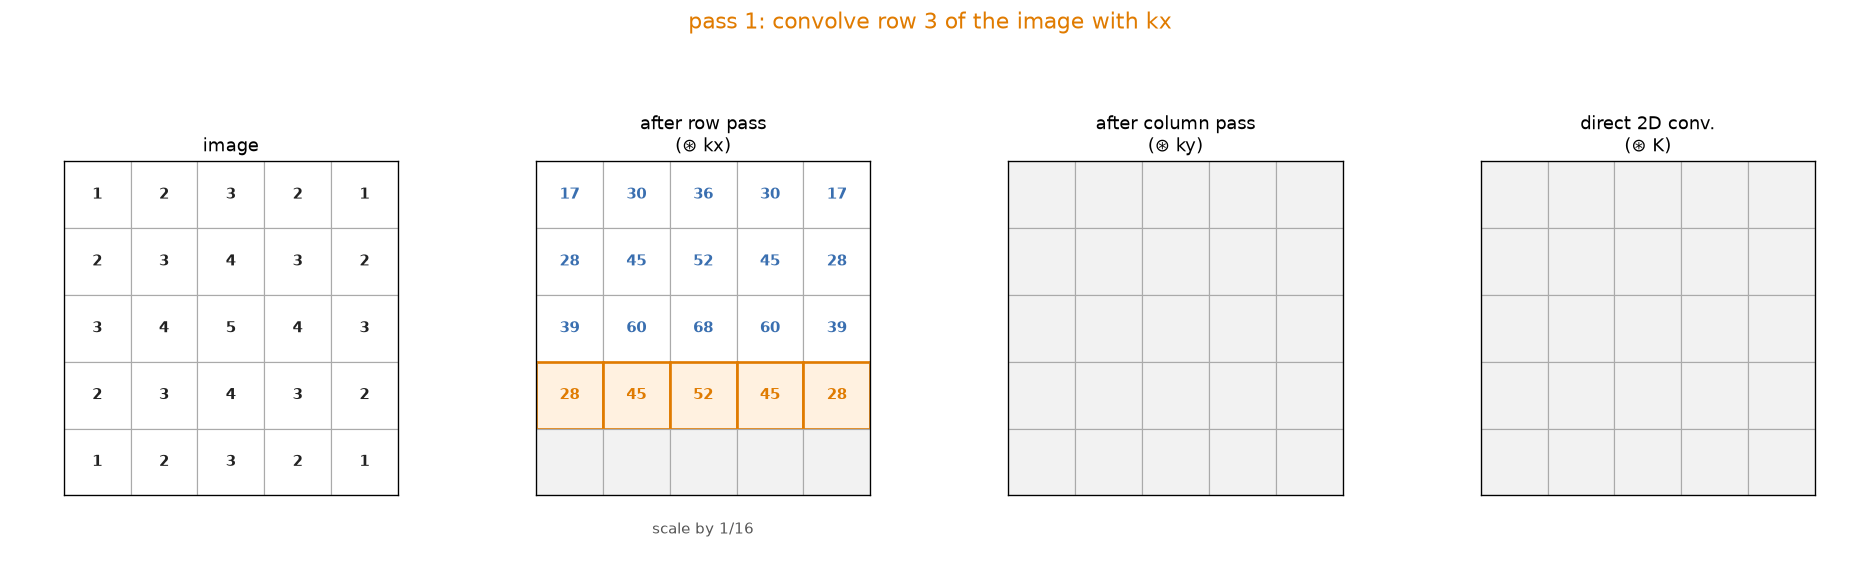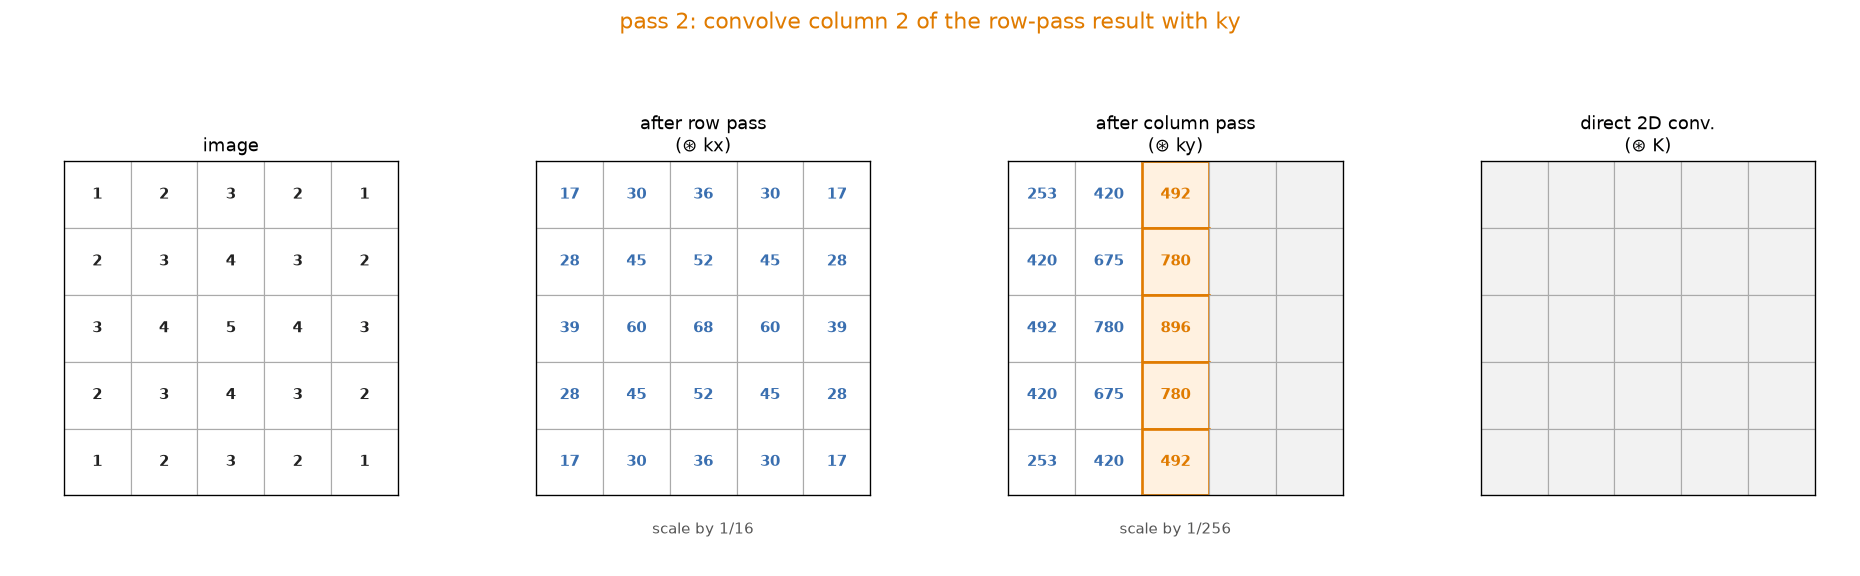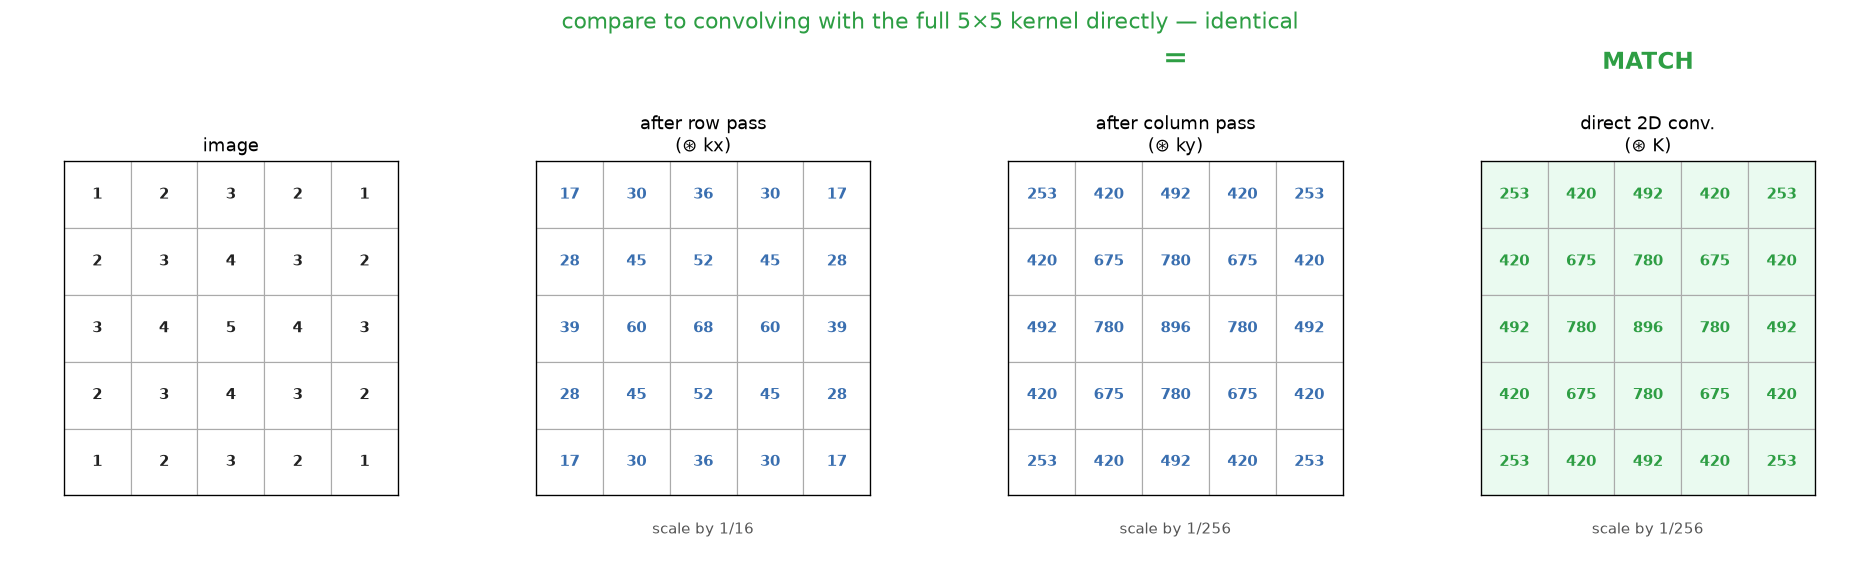
The blur kernel above is separable: it can be written as the outer product of two 1D kernels, $K = k_x \, k_y^\top$. That means convolving with the full $n \times n$ kernel is equivalent to convolving with a $1 \times n$ kernel, then an $n \times 1$ kernel — turning $O(n^2)$ work per pixel into $O(2n)$.
print('1D kernel (k1d_int), scale by 1/16:')
print(k1d_int)
print()
print('2D kernel (outer product of k1d_int), scale by 1/256:')
print(np.outer(k1d_int, k1d_int))
print()

outer_product = np.outer(k1d, k1d)
print('2D kernel == outer product of 1D kernels?', np.allclose(gaussian, outer_product))

separable_result = convolve2d(convolve2d(photo_like, k1d.reshape(1, -1)), k1d.reshape(-1, 1))
full_result = convolve2d(photo_like, gaussian)

print('separable == full 2D convolution?', np.allclose(separable_result, full_result))
This animation shows the 5x5 blur kernel built as an outer product of two 1D kernels (or, equivalently, treating kx as a 1x5 row image and ky as a 5x1 column image and taking their 2D convolution).
This animation shows separable convolution: that kernel applied to the image above as a row pass followed by a column pass. Separable convolution achieves the same result as convolving with the full 2D kernel directly.
Exercises
- Verify that the box kernel is also separable, by writing it as an outer product of two 1D uniform kernels.
sobel_xabove is not symmetric. Compute both the convolution and correlation ofphoto_likewith it, and describe how the two outputs differ (hint: think about which direction of intensity change each responds to).- Time
convolve2dagainstcv2.filter2Don a 300x300 image with a 15x15 Gaussian kernel using%timeit. Then time the separable two-pass version against the full 2D version. How much faster is each speedup?