
Lesson 27: Camera Calibration
Lesson 26 introduced the camera intrinsics matrix $K$ to model a pinhole camera. The classic approach (Zhang, 2000) to camera calibration recovers $K$ by showing the camera a known flat pattern (a checkerboard) from several different angles: extracting a homography (Lesson 24) between the checkerboard plane and each image, then combining constraints from several such homographies to estimate $K$.
import numpy as np
import cv2
import matplotlib.pyplot as plt
What calibration recovers
Camera calibration recovers two separate things:
- Intrinsics $K = \begin{bmatrix}f_x & s & c_x\\0 & f_y & c_y\\0&0&1\end{bmatrix}$: focal lengths, principal point, and skew — the ideal pinhole part of the camera model used throughout Lessons 28 and 29. Skew can safely be assumed to be zero for real cameras.
- Distortion coefficients $(k_1, k_2, p_1, p_2, k_3, \dots)$: real lenses aren't perfect pinholes. Radial distortion ($k_1, k_2, k_3$) bows straight lines into curves (barrel or pincushion, depending on sign); tangential distortion ($p_1, p_2$) accounts for the lens not being perfectly parallel to the sensor. Every equation in Lessons 28 and 29 secretly assumes a pinhole camera model (i.e., distortion is already removed, which requires calibration).
A synthetic calibration rig
We create synthetic images of a camera viewing a checkerboard: define a ground-truth $K$ and distortion, define a flat checkerboard's 3D corner positions, and generate several "photos" of it from different poses by projecting the corners with cv2.projectPoints (which applies distortion exactly as a real lens would). This gives us the same kind of input cv2.calibrateCamera expects from real detected checkerboard corners — while also providing the ground truth to check against.
rng = np.random.default_rng(0)

cols, rows = 9, 6  # internal corners of a 10x7-square checkerboard
corners_3d = np.zeros((rows * cols, 3), dtype=np.float64)
corners_3d[:, :2] = np.mgrid[0:cols, 0:rows].T.reshape(-1, 2)
corners_3d[:, :2] -= corners_3d[:, :2].mean(axis=0)  # center the board on its own origin

K_true = np.array([[800, 0, 320], [0, 800, 240], [0, 0, 1]], dtype=np.float64)
dist_true = np.array([-0.3, 0.1, 0.001, -0.0005, 0.02])  # k1, k2, p1, p2, k3
image_size = (640, 480)

object_points, image_points = [], []
for _ in range(40):
    rvec = rng.uniform(-0.4, 0.4, 3)                                     # a somewhat random tilt
    tvec = np.array([rng.uniform(-0.5, 0.5), rng.uniform(-0.4, 0.4), rng.uniform(9, 13)])
    projected, _ = cv2.projectPoints(corners_3d, rvec, tvec, K_true, dist_true)
    projected = projected.reshape(-1, 2)
    if np.all(projected >= 5) and np.all(projected[:, 0] < image_size[0] - 5) and np.all(projected[:, 1] < image_size[1] - 5):
        object_points.append(corners_3d.astype(np.float32))
        image_points.append(projected.astype(np.float32))

print(f'{len(object_points)} usable synthetic views (out of 40 attempted; some fell outside the frame)')
Rendering synthetic photos
To have something to detect corners in, rather than just point coordinates, we need actual images. Since the checkerboard is flat, the mapping from its own 2D surface pattern to a photo of it is exactly a homography, so warping a picture of the checkerboard (alternating black-and-white squares) through each view's homography synthesizes a photo — standing in for a real photograph.
sq = 60  # pixels per square in the flat target image
board = np.zeros(((rows + 1) * sq, (cols + 1) * sq), dtype=np.uint8)
for r in range(rows + 1):
    for c in range(cols + 1):
        if (r + c) % 2 == 0:
            board[r * sq:(r + 1) * sq, c * sq:(c + 1) * sq] = 255
board_bgr = cv2.cvtColor(board, cv2.COLOR_GRAY2BGR)

# the internal corners' locations in the flat target's own pixel coordinates,
# in the same order as corners_3d
board_pts = np.array([[(c + 1) * sq, (r + 1) * sq] for r in range(rows) for c in range(cols)],
                      dtype=np.float32)

photos = []
for img_pts in image_points:
    H, _ = cv2.findHomography(board_pts, img_pts)
    photos.append(cv2.warpPerspective(board_bgr, H, image_size, borderValue=(128, 128, 128)))
Detecting the target
A real calibration pipeline knows the checkerboard's own flat 2D layout (the physical square size, hence corners_3d's planar grid) — but not the pose of the board in 3D space relative to the camera in each shot (its rotation and translation), and not the 2D pixel positions where its corners land in each photo. So the first step in any calibration pipeline is finding those 2D positions: we run OpenCV's cv2.findChessboardCorners on each photo — exactly as we would on a real photograph — and compare its detections against the ground-truth image_points we already know.
detected_object_points, detected_image_points = [], []
corner_errors = []
example_photo = example_corners_raw = None

for obj_pts, img_pts, photo in zip(object_points, image_points, photos):
    gray = cv2.cvtColor(photo, cv2.COLOR_BGR2GRAY)

    found, corners = cv2.findChessboardCorners(gray, (cols, rows))
    if not found:
        continue
    corners = cv2.cornerSubPix(gray, corners, (11, 11), (-1, -1),
                                (cv2.TERM_CRITERIA_EPS + cv2.TERM_CRITERIA_MAX_ITER, 30, 0.001))

    if example_photo is None:
        example_photo, example_corners_raw = photo, corners

    corners = corners.reshape(-1, 2)[::-1]  # cv2 scans from the opposite corner vs. our board_pts order
    detected_object_points.append(obj_pts)
    detected_image_points.append(corners.astype(np.float32))
    corner_errors.append(np.linalg.norm(corners - img_pts, axis=1).mean())

print(f'corners detected in {len(detected_image_points)} / {len(image_points)} synthetic photos')
print(f'mean per-view corner error vs. ground truth: {np.mean(corner_errors):.2f} px '
      f'(max {np.max(corner_errors):.2f} px)')

example_annotated = example_photo.copy()
cv2.drawChessboardCorners(example_annotated, (cols, rows), example_corners_raw, True)

fig, axes = plt.subplots(1, 2, figsize=(8, 4))
axes[0].imshow(board, cmap='gray')
axes[0].set_title('Flat checkerboard target')
axes[0].axis('off')
axes[1].imshow(cv2.cvtColor(example_annotated, cv2.COLOR_BGR2RGB))
axes[1].set_title('cv2.findChessboardCorners,\none synthetic photo')
axes[1].axis('off')
plt.tight_layout()
plt.show()

Running calibration
Zhang's calibration algorithm (cv2.calibrateCamera) takes the known corner positions on the checkerboard and their detected 2D image positions across all views, and jointly solves for $K$, distortion, and each view's own pose.
rms_error, K_estimated, dist_estimated, rvecs, tvecs = cv2.calibrateCamera(
    detected_object_points, detected_image_points, image_size, None, None)

print(f'RMS reprojection error: {rms_error:.2e} pixels\n')
print('K (true):\n', K_true)
print('K (estimated):\n', np.round(K_estimated, 3))
print()
print('distortion (true):     ', dist_true)
print('distortion (estimated):', np.round(dist_estimated.ravel(), 5))
Using noisy corner detections, calibration does not recover the ground truth parameters exactly. We measure the quality of the calibration as reprojection error. This is why in practice you'd use as many views, from as wide a variety of angles, as practical: more (and more diverse) constraints average out detector noise and better constrain the estimation.
Straight lines, bent by a lens
Lens distortion causes straight lines to become curved. In normalized (pre-$K$) camera coordinates:
$$x_d = x(1 + k_1r^2 + k_2r^4 + k_3r^6) + 2p_1xy + p_2(r^2+2x^2)$$ $$y_d = y(1 + k_1r^2 + k_2r^4 + k_3r^6) + p_1(r^2+2y^2) + 2p_2xy$$
where $r^2 = x^2+y^2$. This is exactly the model cv2.projectPoints applied internally above.
def distort_normalized(xy, dist):
    k1, k2, p1, p2, k3 = dist
    x, y = xy[:, 0], xy[:, 1]
    r2 = x**2 + y**2
    radial = 1 + k1 * r2 + k2 * r2**2 + k3 * r2**3
    xd = x * radial + 2 * p1 * x * y + p2 * (r2 + 2 * x**2)
    yd = y * radial + p1 * (r2 + 2 * y**2) + 2 * p2 * x * y
    return np.stack([xd, yd], axis=1)

def make_grid_lines():
    lines = []
    for xv in np.linspace(-0.38, 0.38, 9):
        ys = np.linspace(-0.28, 0.28, 50)
        lines.append(np.stack([np.full_like(ys, xv), ys], axis=1))
    for yv in np.linspace(-0.28, 0.28, 7):
        xs = np.linspace(-0.38, 0.38, 50)
        lines.append(np.stack([xs, np.full_like(xs, yv)], axis=1))
    return lines

def draw_lines(lines_px, height=480, width=640):
    img = np.full((height, width, 3), 255, dtype=np.uint8)
    for line in lines_px:
        for i in range(len(line) - 1):
            cv2.line(img, tuple(line[i].astype(int)), tuple(line[i + 1].astype(int)), (0, 0, 0), 1)
    return img

grid_lines_normalized = make_grid_lines()

straight_px = [line @ K_true[:2, :2].T + K_true[:2, 2] for line in grid_lines_normalized]
distorted_px = [distort_normalized(line, dist_true) @ K_true[:2, :2].T + K_true[:2, 2]
                for line in grid_lines_normalized]

fig, axes = plt.subplots(1, 2, figsize=(9, 4))
axes[0].imshow(draw_lines(straight_px))
axes[0].set_title('Ideal pinhole (no distortion)')
axes[1].imshow(draw_lines(distorted_px))
axes[1].set_title(f'Through the lens\n(k1={dist_true[0]}, k2={dist_true[1]})')
for ax in axes:
    ax.axis('off')
plt.tight_layout()
plt.show()

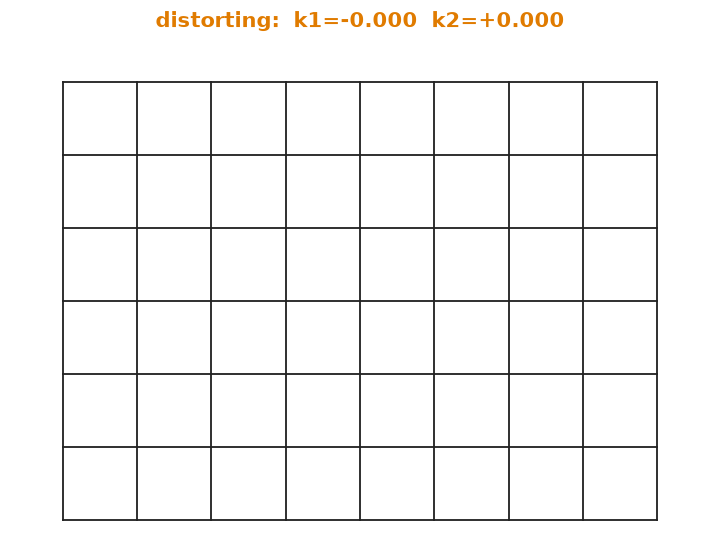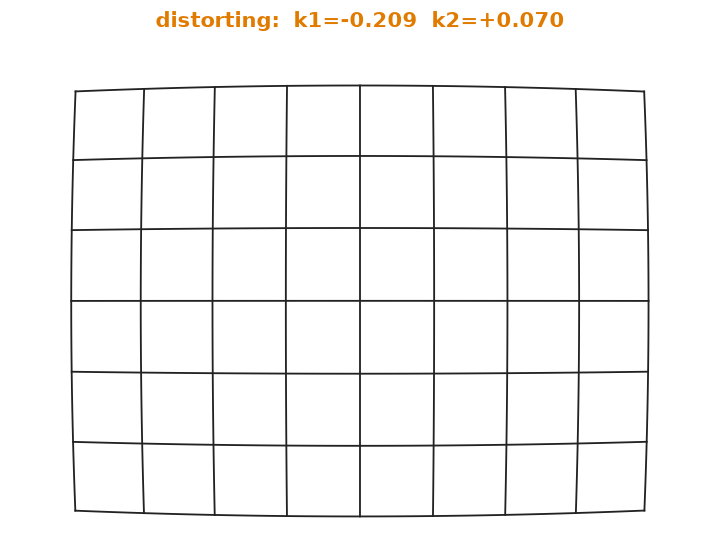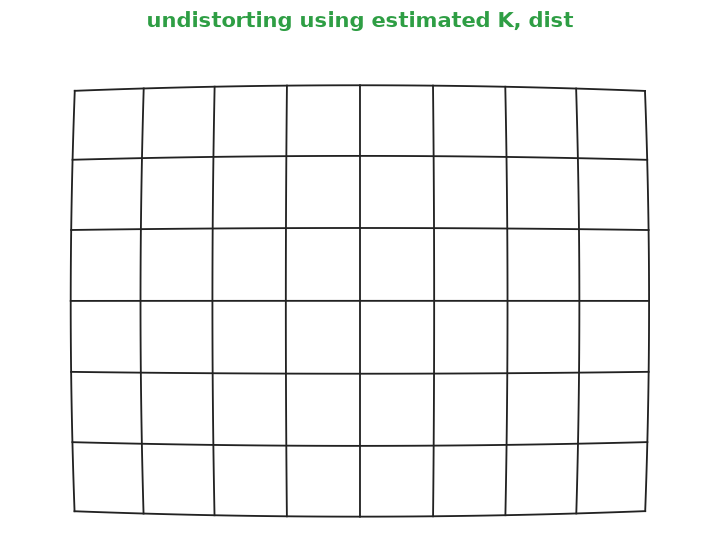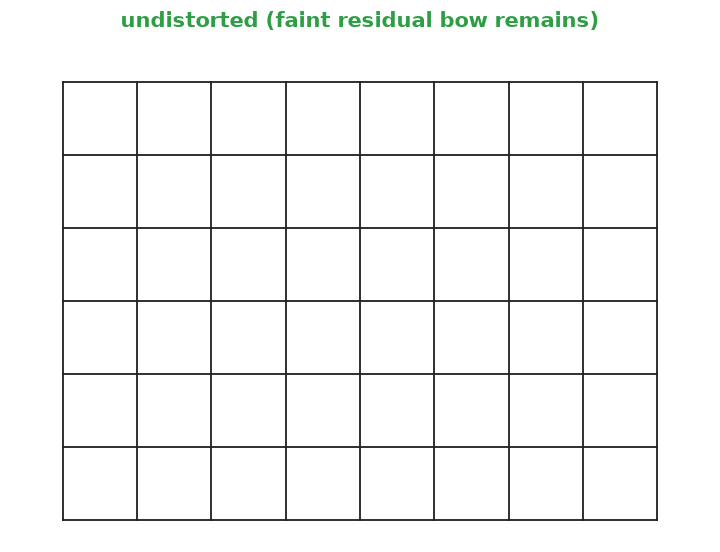
This animation shows the distortion build up continuously (k1, k2 ramping from 0 to their true values, bowing the grid), then shows the undistortion step pulling the bent grid back toward straight using the estimated calibration — the same two results plotted above, now as a single continuous transition.
Undoing distortion with the estimated parameters
cv2.undistortPoints inverts the distortion model, converting distorted pixel coordinates back to normalized undistorted coordinates. Applying it to the bent grid lines above, using our estimated (not the true) calibration, should straighten them back out.
undistorted_normalized = [
    cv2.undistortPoints(px.reshape(-1, 1, 2).astype(np.float64), K_estimated, dist_estimated).reshape(-1, 2)
    for px in distorted_px
]
undistorted_px = [line @ K_estimated[:2, :2].T + K_estimated[:2, 2] for line in undistorted_normalized]

fig, axes = plt.subplots(1, 2, figsize=(9, 4))
axes[0].imshow(draw_lines(distorted_px))
axes[0].set_title('Distorted (as captured)')
axes[1].imshow(draw_lines(undistorted_px))
axes[1].set_title('Undistorted using estimated K, dist')
for ax in axes:
    ax.axis('off')
plt.tight_layout()
plt.show()

original_normalized = np.concatenate(grid_lines_normalized)
recovered_normalized = np.concatenate(undistorted_normalized)
print(f'max recovery error (normalized coords): {np.abs(original_normalized - recovered_normalized).max():.2e}')

The lines straighten out, though not perfectly — a faint bow remains, since K_estimated/dist_estimated are themselves only approximately correct. This process of calibrating a real camera should be performed, if possible, before handing real photos to any of the geometric machinery from Lessons 28 and 29, all of which implicitly assumes an ideal, distortion-free pinhole model. Keep in mind, however, that many modern pipelines perform auto-calibration without checkerboard images, using simplified camera models (typically just one focal length parameter — ignoring aspect ratio, non-central principal point, and lens distortion).
Exercises
- Add extra synthetic pixel noise (e.g.
rng.normal(0, 0.5, corners.shape)) on top of the real detector noise, to each view's detected corners before calibrating. How much does the RMS reprojection error grow, and how doesK_estimateddrift further fromK_true? - This setup ends with only a handful of successfully-detected views (printed above). Try reducing
detected_object_points/detected_image_pointsdown to just 3 views before calibrating. Does the estimate noticeably degrade, especially for the distortion coefficients (which need corners spread widely across the frame, including near the edges, to be well constrained)? - Set
dist_true = np.zeros(5)(a perfect pinhole, no distortion) and rerun the whole notebook. Confirm the "distorted" and "ideal" grids become identical, and that calibration still recoversK_truereasonably well even with zero distortion to estimate.