
Lesson 32: Multi-Layer Perceptrons
Lesson 31's single neuron, trained however carefully, could not beat chance on the ring-inside-a-disk dataset — a single linear projection just isn't expressive enough. This lesson adds one more layer: instead of one projection followed by a threshold, use two projections with a nonlinearity in between. That's it. That's the entire idea behind every deep network in this course — stack more of these.
import numpy as np
import torch
import matplotlib.pyplot as plt
The unsolvable problem, again
rng = np.random.default_rng(0)
theta_in = rng.uniform(0, 2 * np.pi, 60)
inner = np.stack([0.5 * np.cos(theta_in), 0.5 * np.sin(theta_in)], axis=1) + rng.normal(0, 0.1, (60, 2))
theta_out = rng.uniform(0, 2 * np.pi, 60)
outer = np.stack([2.0 * np.cos(theta_out), 2.0 * np.sin(theta_out)], axis=1) + rng.normal(0, 0.15, (60, 2))
X = np.vstack([inner, outer])
y = np.concatenate([np.zeros(60), np.ones(60)])

plt.scatter(*inner.T, s=15, label='inner (y=0)')
plt.scatter(*outer.T, s=15, label='outer (y=1)')
plt.legend(fontsize=8)
plt.gca().set_aspect('equal')
plt.title('No single linear projection separates these (Lessons 30-31)')
plt.show()

Two projections, one nonlinearity
A multi-layer perceptron (MLP) chains a hidden projection into a new space, a nonlinear activation applied elementwise, and then a final linear projection (exactly Lesson 31's neuron) on top of the transformed coordinates:
$$h = \text{ReLU}(W_1 x + b_1), \qquad z = w_2^\top h + b_2, \qquad p = \sigma(z)$$
$\text{ReLU}(u) = \max(0, u)$ is the simplest common activation: it's linear everywhere except a single kink at zero. That one kink, applied independently to every unit of $h$, is enough — the hidden layer can bend, fold, and stretch the input space so a linear boundary in the transformed space corresponds to a highly nonlinear boundary back in the original coordinates.
ReLU and sigmoid are two different activations doing different jobs here: ReLU is the hidden-layer nonlinearity, reshaping the input space so the points become easier to separate, while sigmoid (carried over unchanged from Lesson 31) squashes the final score $z$ into a probability at the end. Their shapes look fairly similar (plot below), but each is suited to its own role: ReLU's unbounded output and simple derivative work well buried inside a network, while sigmoid's output confined to (0, 1) makes it readable as a probability at the output.
zz = np.linspace(-5, 5, 200)
fig, axes = plt.subplots(1, 2, figsize=(9, 3.5))
axes[0].plot(zz, np.maximum(0, zz))
axes[0].set_title('ReLU (hidden-layer activation)')
axes[0].set_xlabel('u')
axes[0].set_ylabel('ReLU(u)')
axes[1].plot(zz, 1 / (1 + np.exp(-zz)))
axes[1].set_title('sigmoid (output activation)')
axes[1].set_xlabel('z')
axes[1].set_ylabel('sigma(z)')
plt.tight_layout()
plt.show()

Why the nonlinearity is essential
Without ReLU — if the hidden layer were left as plain $h = W_1 x + b_1$ — the two layers would collapse into a single linear projection:
$$z = w_2^\top(W_1 x + b_1) + b_2 = \underbrace{(w_2^\top W_1)}_{w'^\top} x + \underbrace{(w_2^\top b_1 + b_2)}_{b'}$$
That's exactly Lesson 31's single neuron again, just with the two layers' weights multiplied together into one $w'$ and $b'$. This is the flip side of Lesson 30's observation that matrix multiplication is projection, stacked: composing two matrix multiplications is still just one matrix multiplication, so stacking purely linear layers buys nothing, no matter how many you chain. ReLU's kink is what breaks that collapse: because it isn't a linear function, $w_2^\top \text{ReLU}(W_1x+b_1)+b_2$ cannot be rewritten as $w'^\top x + b'$.
demo_rng = np.random.default_rng(3)
W1_demo = demo_rng.normal(size=(2, 4))
b1_demo = demo_rng.normal(size=4)
W2_demo = demo_rng.normal(size=(4, 1))
b2_demo = demo_rng.normal(size=1)

z_two_linear_layers = (X @ W1_demo + b1_demo) @ W2_demo + b2_demo   # no nonlinearity in between

W_combined = W1_demo @ W2_demo                # a single (2, 1) matrix
b_combined = b1_demo @ W2_demo + b2_demo      # a single offset
z_one_combined_layer = X @ W_combined + b_combined

print(f'max diff, two LINEAR layers vs. one combined layer: '
      f'{np.abs(z_two_linear_layers - z_one_combined_layer).max():.2e}')
Backprop through two layers
The chain rule extends cleanly: propagate the error signal $\partial L/\partial z$ from Lesson 31 backward through the output projection to get $\partial L/\partial h$, then backward through the ReLU and the hidden projection to get $\partial L/\partial W_1, \partial L/\partial b_1$. Every step is either "multiply by a weight matrix's transpose" or "multiply elementwise by an activation's derivative" — stacking more layers just repeats these same two operations further back through the chain.
def sigmoid(z):
    return 1 / (1 + np.exp(-z))

def relu(z):
    return np.maximum(0, z)

def relu_deriv(z):
    return (z > 0).astype(np.float64)

def forward(X, W1, b1, W2, b2):
    z1 = X @ W1 + b1
    a1 = relu(z1)
    z2 = (a1 @ W2 + b2).ravel()
    p = sigmoid(z2)
    return p, (z1, a1, z2)

def backward(X, y, p, cache, W2):
    z1, a1, z2 = cache
    n = len(y)
    grad_z2 = ((p - y) / n).reshape(-1, 1)
    grad_W2 = a1.T @ grad_z2
    grad_b2 = grad_z2.sum(axis=0)
    grad_a1 = grad_z2 @ W2.T
    grad_z1 = grad_a1 * relu_deriv(z1)
    grad_W1 = X.T @ grad_z1
    grad_b1 = grad_z1.sum(axis=0)
    return grad_W1, grad_b1, grad_W2, grad_b2
Sanity check against PyTorch autograd
H = 4
init_rng = np.random.default_rng(8)
W1 = init_rng.normal(size=(2, H)) * 0.7
b1 = np.zeros(H)
W2 = init_rng.normal(size=(H, 1)) * 0.7
b2 = np.zeros(1)

p, cache = forward(X, W1, b1, W2, b2)
grad_W1, grad_b1, grad_W2, grad_b2 = backward(X, y, p, cache, W2)

X_t = torch.tensor(X)
y_t = torch.tensor(y)
W1_t = torch.tensor(W1, requires_grad=True)
b1_t = torch.tensor(b1, requires_grad=True)
W2_t = torch.tensor(W2, requires_grad=True)
b2_t = torch.tensor(b2, requires_grad=True)

z1_t = X_t @ W1_t + b1_t
a1_t = torch.relu(z1_t)
z2_t = (a1_t @ W2_t + b2_t).squeeze(-1)
loss_t = torch.nn.functional.binary_cross_entropy_with_logits(z2_t, y_t)
loss_t.backward()

print(f'W1 max diff: {np.abs(grad_W1 - W1_t.grad.numpy()).max():.2e}')
print(f'W2 max diff: {np.abs(grad_W2 - W2_t.grad.numpy()).max():.2e}')
print(f'b1 max diff: {np.abs(grad_b1 - b1_t.grad.numpy()).max():.2e}')
print(f'b2 max diff: {np.abs(grad_b2 - b2_t.grad.numpy()).max():.2e}')
Training
Same recipe as Lesson 31 -- forward pass, loss, backward pass, step against the gradient -- just with four parameter tensors ($W_1, b_1, W_2, b_2$) updated each epoch instead of two. Loss keeps shrinking toward (but never exactly reaching) zero even after accuracy hits 100%, since confident-and-correct predictions can always get a little more confident.
Watching the loop run, one stage at a time
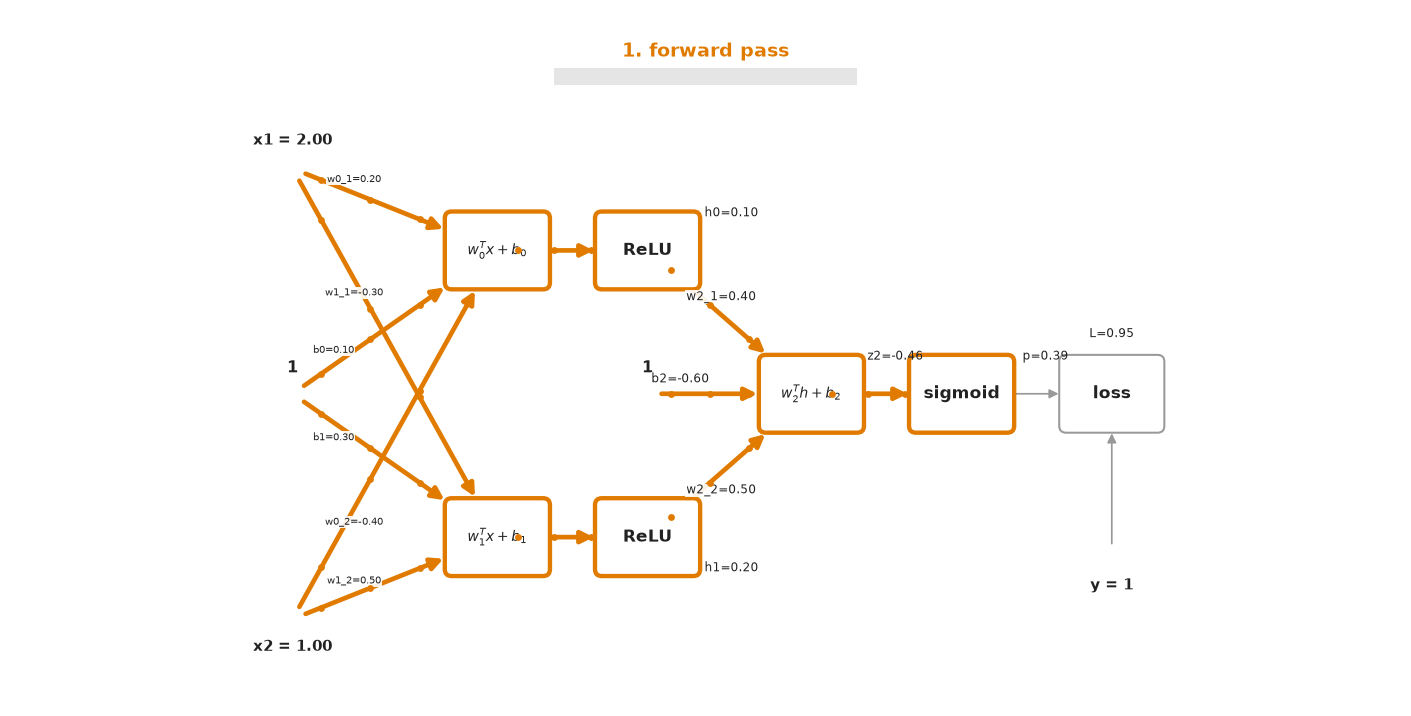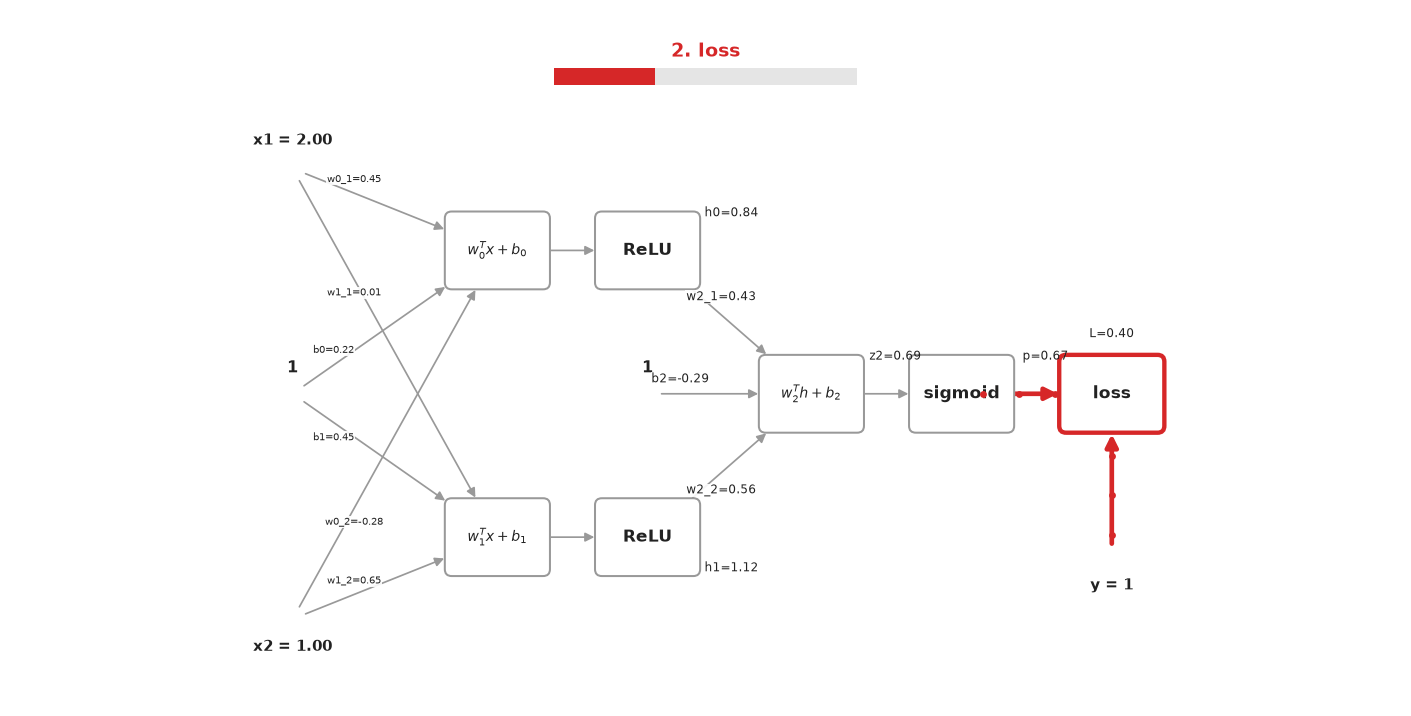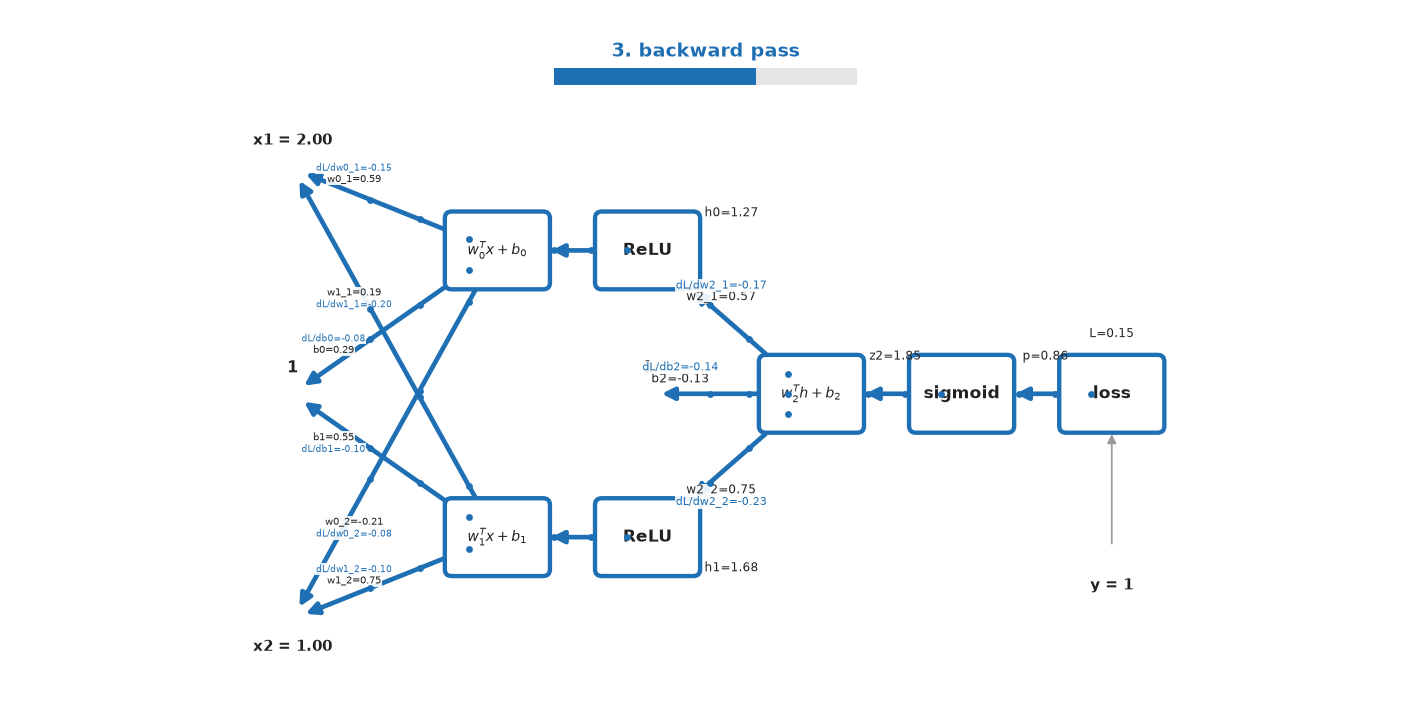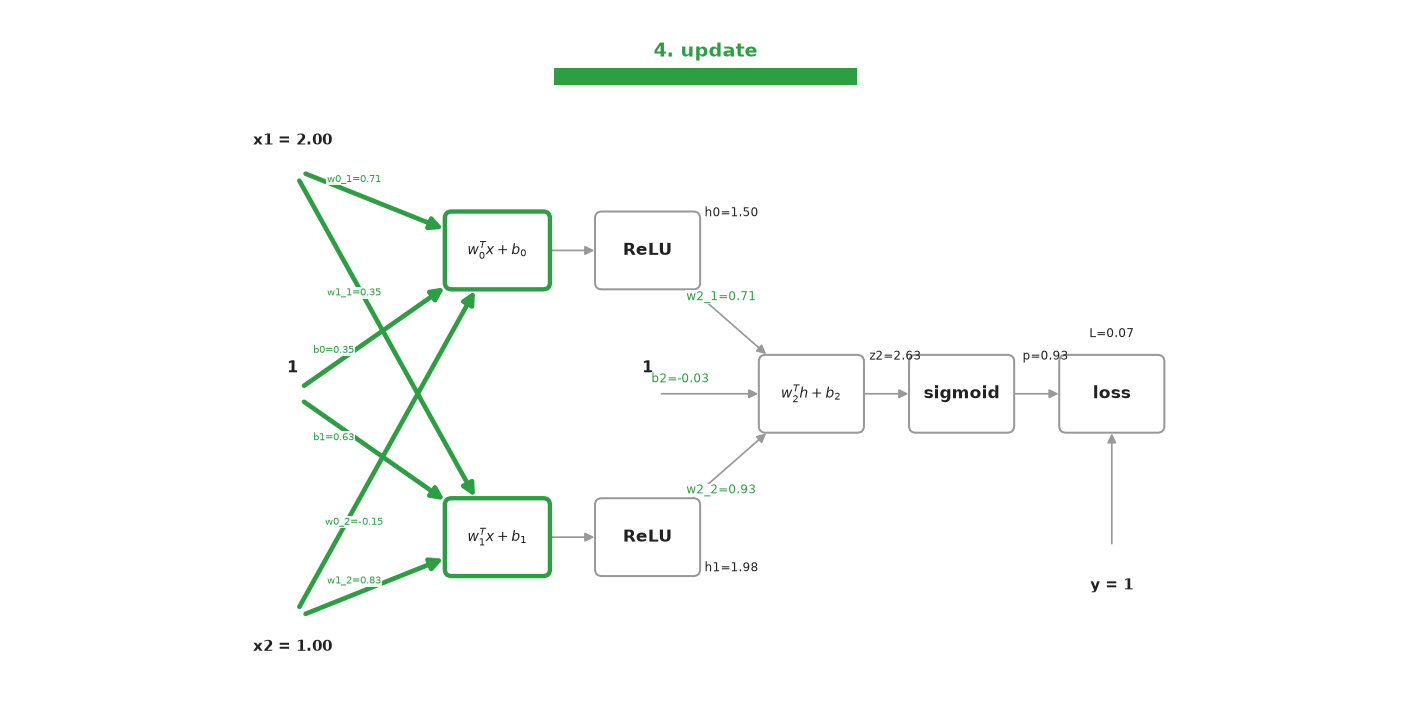
The animation below plays through the same 4-stage recipe — forward pass, loss, backward pass, update — now across two hidden units instead of one, on a hand-picked example (not the real 120-point dataset below): $x=(2, 1)$, $y=1$, hidden units $w_0=(0.2,-0.4)$, $b_0=0.1$ and $w_1=(-0.3,0.5)$, $b_1=0.3$, output layer $w_2=(0.4,0.5)$, $b_2=-0.6$, $\eta=0.5$. As in Lesson 31's version, the checkpoints are consecutive steps (no gaps), so every number is reproducible by hand.
Working the first step out by hand:
$$z_0 = w_0\cdot x+b_0 = (0.2)(2)+(-0.4)(1)+0.1=0.1, \qquad h_0=\text{ReLU}(z_0)=0.1$$ $$z_1 = w_1\cdot x+b_1 = (-0.3)(2)+(0.5)(1)+0.3=0.2, \qquad h_1=\text{ReLU}(z_1)=0.2$$ $$z_2 = w_2\cdot h+b_2 = (0.4)(0.1)+(0.5)(0.2)-0.6=-0.46$$ $$p=\sigma(-0.46)\approx0.387, \qquad L=-\log(p)\approx0.949$$
Backward, worked out for hidden unit 0 (unit 1 and the output layer follow exactly the same pattern — left as an exercise):
$$\frac{\partial L}{\partial z_2}=p-y\approx-0.613$$ $$\frac{\partial L}{\partial h_0}=\frac{\partial L}{\partial z_2}\cdot w_{2,0}\approx-0.245, \qquad \frac{\partial L}{\partial z_0}=\frac{\partial L}{\partial h_0}\cdot\text{ReLU}'(z_0)\approx-0.245 \quad(\text{since } z_0>0)$$ $$\frac{\partial L}{\partial w_{0,1}}=x_1\cdot\frac{\partial L}{\partial z_0}\approx-0.490, \qquad \frac{\partial L}{\partial w_{0,2}}\approx-0.245, \qquad \frac{\partial L}{\partial b_0}\approx-0.245$$ $$w_{0,1} \leftarrow 0.2-0.5(-0.490)\approx0.445, \qquad w_{0,2} \leftarrow -0.4-0.5(-0.245)\approx-0.277, \qquad b_0 \leftarrow 0.1-0.5(-0.245)\approx0.223$$
That's exactly what the animation shows after its first update.
Back to the real dataset
With the two-hidden-unit mechanics confirmed by hand, the rest of this section goes back to the real network: $H=4$ hidden units, trained on the full ring-vs-disk dataset from earlier in this lesson.
lr = 0.1
losses = []
for epoch in range(3000):
    p, cache = forward(X, W1, b1, W2, b2)
    eps = 1e-9
    losses.append(-np.mean(y * np.log(p + eps) + (1 - y) * np.log(1 - p + eps)))
    grad_W1, grad_b1, grad_W2, grad_b2 = backward(X, y, p, cache, W2)
    W1 -= lr * grad_W1; b1 -= lr * grad_b1
    W2 -= lr * grad_W2; b2 -= lr * grad_b2

final_pred = (p > 0.5).astype(float)
print(f'final accuracy: {(final_pred == y).mean():.1%}  (cf. single neuron from Lesson 31 managed 50%)')
print(f'final loss: {losses[-1]:.4f}')

plt.plot(losses)
plt.xlabel('epoch'); plt.ylabel('loss')
plt.title('Training loss (2-layer MLP)')
plt.show()

The hidden layer's projections, made visible
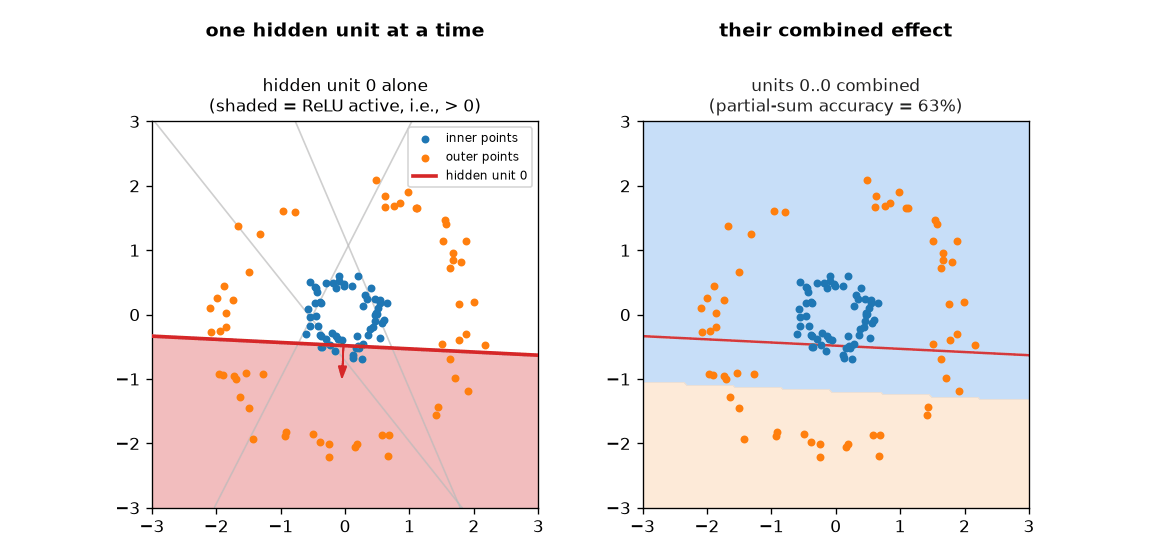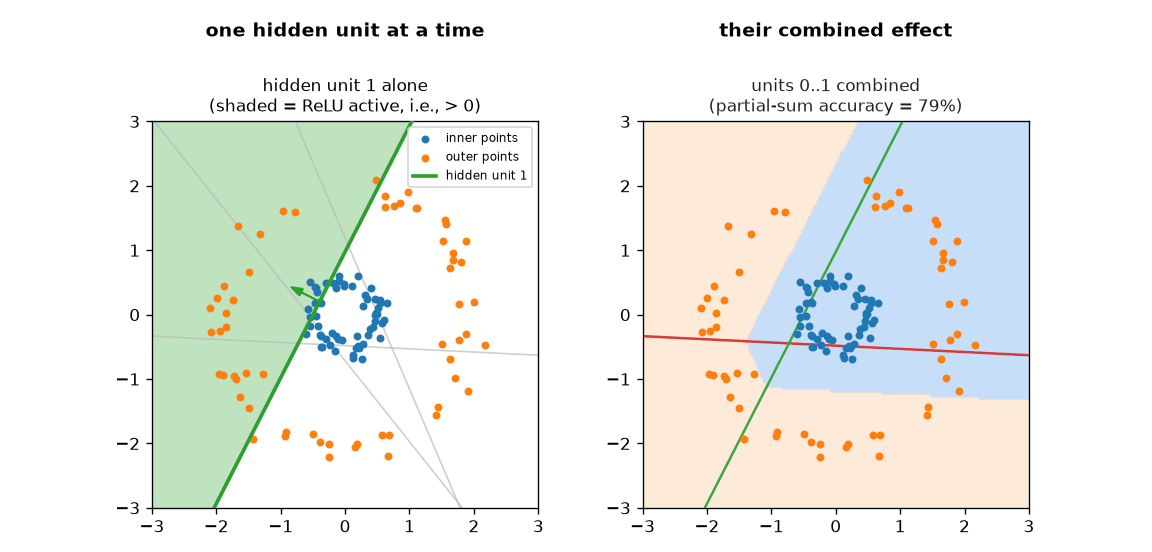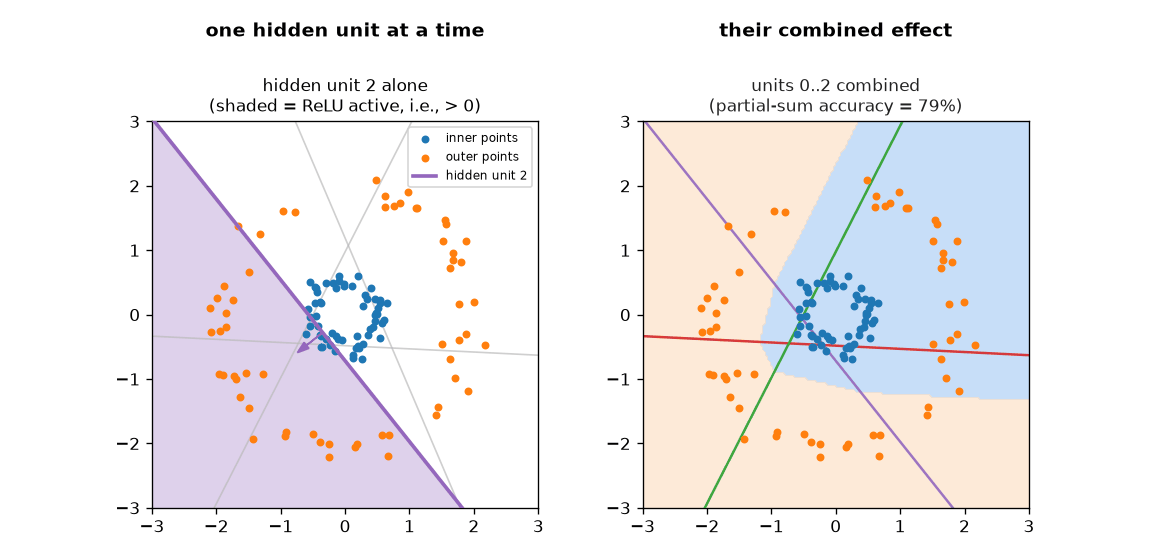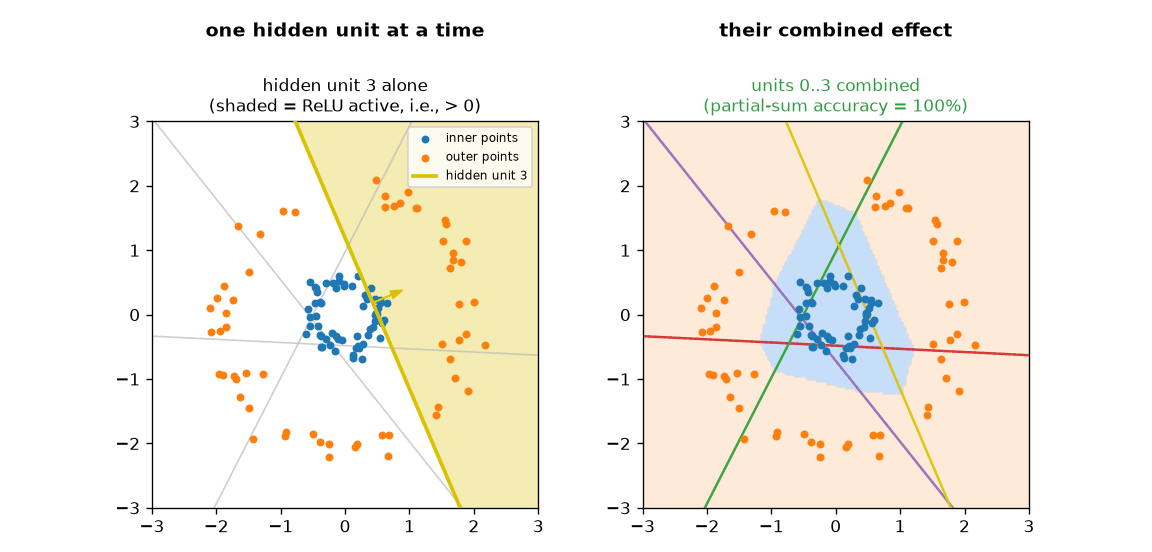
Each hidden unit is itself a Lesson 30-style projection: a direction $w_i$ (one column of $W_1$) and an offset $b_i$ (one entry of $b_1$), together defining a cut $w_i \cdot x + b_i = 0$ with ReLU zeroing out everything on one side of it. With only 2 input dimensions, all $H$ of these can be drawn directly over the original data.
fig, ax = plt.subplots(figsize=(5, 5))
ax.scatter(*X[y == 0].T, s=15, label='inner')
ax.scatter(*X[y == 1].T, s=15, label='outer')

colors = plt.cm.tab10.colors
for i in range(W1.shape[1]):
    w_i, b_i = W1[:, i], b1[i]
    # the cut {x : w_i.x + b_i = 0}, drawn through its closest point to the origin
    foot = -b_i * w_i / (w_i @ w_i)
    perp = np.array([-w_i[1], w_i[0]])
    p1, p2 = foot + 5 * perp, foot - 5 * perp
    ax.plot([p1[0], p2[0]], [p1[1], p2[1]], color=colors[i], linewidth=1.5, label=f'hidden unit {i}')
    ax.arrow(*foot, *(w_i / np.linalg.norm(w_i) * 0.5), head_width=0.1, color=colors[i], length_includes_head=True)

ax.set_xlim(-3, 3); ax.set_ylim(-3, 3)
ax.set_aspect('equal')
ax.legend(fontsize=7, loc='upper right')
ax.set_title('Each hidden unit is one projection direction $w_i$,\ncutting the space along $w_i \\cdot x + b_i = 0$')
plt.tight_layout()
plt.show()

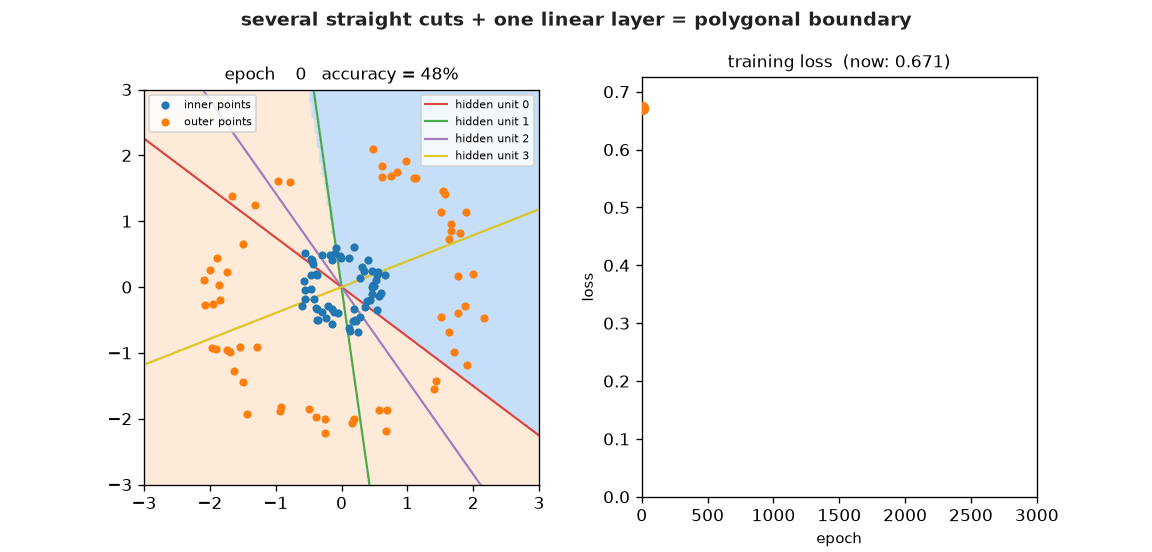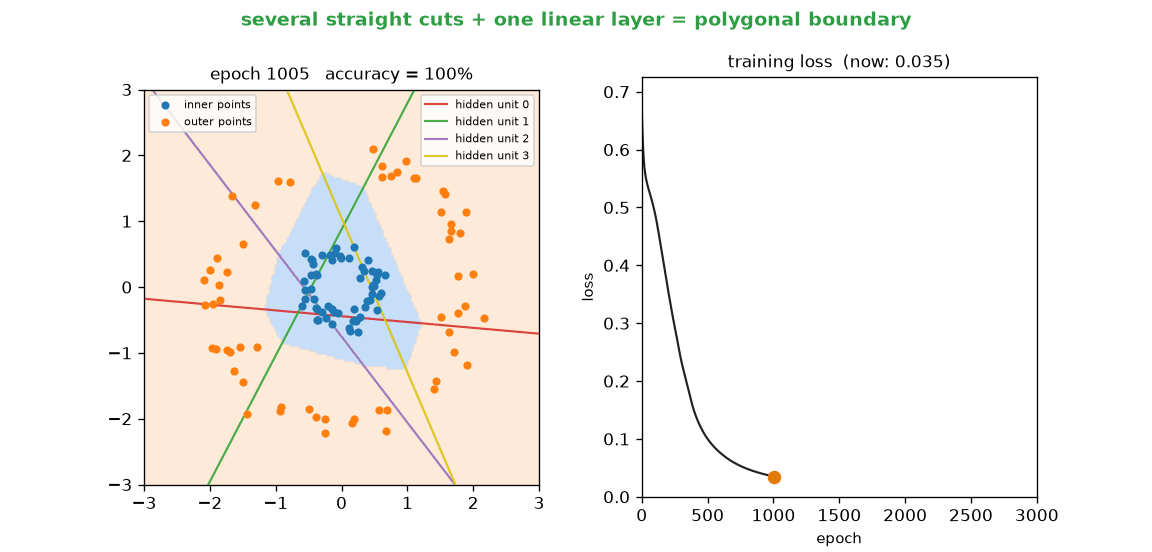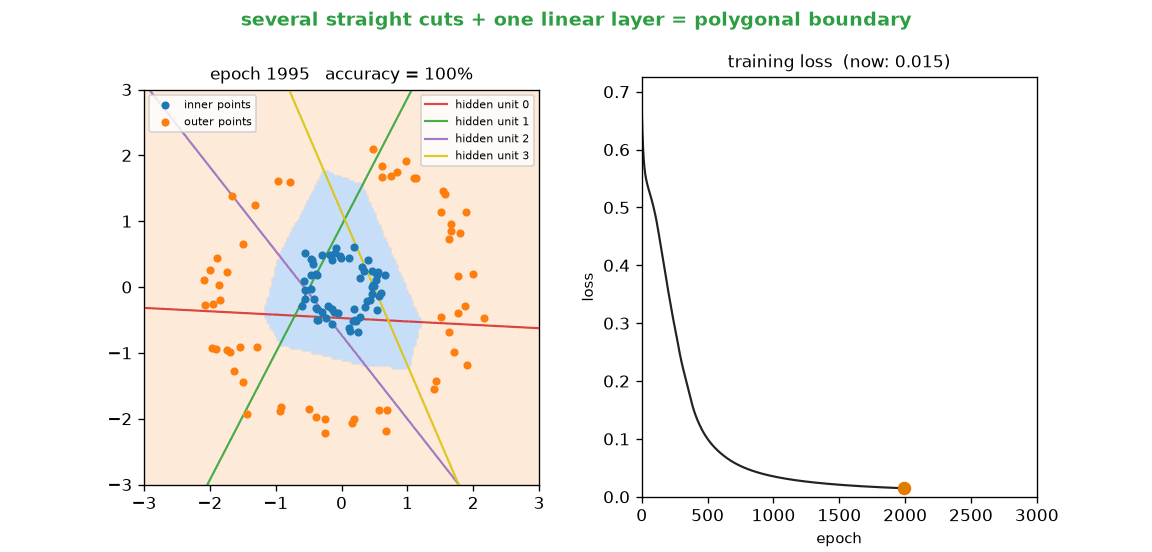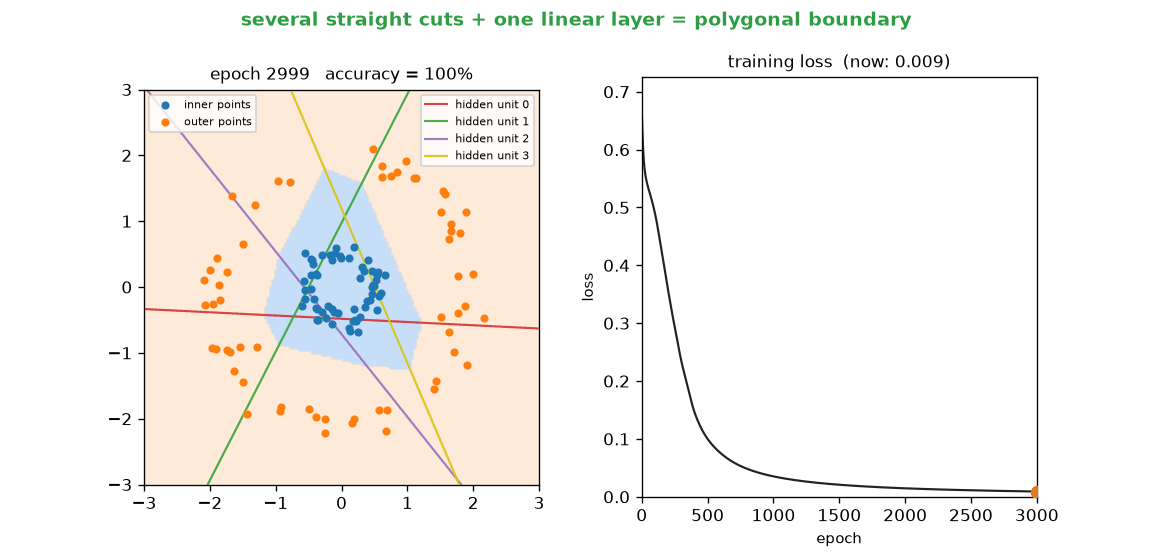
On its own, each cut is just a straight line — no single one of them separates the ring from the disk. But the output layer combines all $H$ of their (ReLU'd) results together, and a handful of straight cuts arranged around the ring, combined with the right weights, can approximate a closed curve well enough to enclose it. That combining step is exactly what the rest of this section visualizes.
This animation runs the full training loop, redrawing all four hidden-unit cuts and the combined decision region (shaded) together on every checkpoint. At epoch 0 the four lines and the shaded region are essentially arbitrary; by the end, the four cuts have rotated and shifted so their shaded intersection is a tight polygon hugging the inner disk almost exactly — several straight lines, combined through one more linear layer, bending into a closed curve.
Once training has converged, freeze the weights and look at the four hidden units one at a time. The left panel shows a single unit in isolation: its cut and the half-plane where it's "on" (ReLU output > 0). The right panel shows the partial forward pass through the (frozen) output layer (the not-yet-introduced units' contributions are zeroed out of the sum), so by the last step it lands exactly on the network's actual decision boundary.
What the hidden layer actually did
The output layer is just a linear projection (Lesson 31's neuron) — but it acts on $h$, the hidden layer's output, not on the original $x$. If the hidden layer did its job, the transformed points should already be much easier to separate with a straight line. Since $h$ lives in $\mathbb{R}^4$ here, we use PCA (Lesson 6) to visualize it in 2D.
_, (_, hidden, _) = forward(X, W1, b1, W2, b2)

hidden_centered = hidden - hidden.mean(axis=0)
cov = np.cov(hidden_centered.T)
eigvals, eigvecs = np.linalg.eigh(cov)
top2_directions = eigvecs[:, -2:]
hidden_2d = hidden_centered @ top2_directions

fig, axes = plt.subplots(1, 2, figsize=(9, 4))
axes[0].scatter(*X[y == 0].T, s=15, label='inner')
axes[0].scatter(*X[y == 1].T, s=15, label='outer')
axes[0].set_aspect('equal')
axes[0].set_title('Original input space')
axes[0].legend(fontsize=7)

axes[1].scatter(*hidden_2d[y == 0].T, s=15, label='inner')
axes[1].scatter(*hidden_2d[y == 1].T, s=15, label='outer')
axes[1].set_title('Hidden representation\n(top 2 PCA directions of a 4D space)')
axes[1].legend(fontsize=7)
plt.tight_layout()
plt.show()

Even this lossy 2D snapshot of the full 4D hidden space shows the two classes pulled apart into something close to linearly separable — a big improvement over the 74% ceiling that was the best any line could do in the original space (Lesson 30). The actual output neuron works in the full 4D hidden space, where it achieves 100% accuracy exactly. This is the entire mechanism of deep learning in miniature: each layer reshapes the space so that the next layer's job gets easier, until the final layer's job is trivial — a single linear projection.
Model capacity: how many hidden units are enough?
A model's capacity is how rich a family of functions it can represent. Here that's set directly by $H$, the hidden layer's width: each hidden unit contributes one straight cut (Lesson 30-style), and the output layer combines these units. Too few units, and the model simply cannot represent the boundary needed by the dataset — no amount of training can find a solution that doesn't exist. Sweep $H$ and retrain from scratch at each width, across several random initializations, to see the ceiling directly.
def train_and_eval(H, seed, epochs=3000, lr=0.1):
    init_rng = np.random.default_rng(seed)
    W1_s = init_rng.normal(size=(2, H)) * 0.7
    b1_s = np.zeros(H)
    W2_s = init_rng.normal(size=(H, 1)) * 0.7
    b2_s = np.zeros(1)
    for _ in range(epochs):
        p, cache = forward(X, W1_s, b1_s, W2_s, b2_s)
        gW1, gb1, gW2, gb2 = backward(X, y, p, cache, W2_s)
        W1_s -= lr * gW1; b1_s -= lr * gb1
        W2_s -= lr * gW2; b2_s -= lr * gb2
    p, _ = forward(X, W1_s, b1_s, W2_s, b2_s)
    return ((p > 0.5).astype(float) == y).mean()

widths = [1, 2, 3, 4, 6, 8, 16]
seeds = range(5)
mean_accs, min_accs, max_accs = [], [], []
for H_test in widths:
    accs = [train_and_eval(H_test, seed) for seed in seeds]
    mean_accs.append(np.mean(accs)); min_accs.append(np.min(accs)); max_accs.append(np.max(accs))
    print(f'H={H_test:>2}: mean acc={np.mean(accs):.1%}  (min={np.min(accs):.1%}, max={np.max(accs):.1%}, over {len(seeds)} seeds)')

plt.figure(figsize=(5.5, 3.5))
plt.plot(widths, mean_accs, '-o', label='mean')
plt.fill_between(widths, min_accs, max_accs, alpha=0.2, label='min-max range')
plt.xlabel('hidden units ($H$)'); plt.ylabel('final accuracy')
plt.title('Accuracy vs. capacity, across 5 random seeds each')
plt.legend(fontsize=8)
plt.show()

$H=1$ caps out well below 100% no matter how long it trains or which seed it starts from — that's not an optimization failure, it's a representational ceiling: one hidden unit is just a single cut, so it inherits Lesson 30's ~74% linear limit almost exactly.
$H=2$ is better, but it is still capacity-limited — none of the five seeds above reach 100%.
$H=3$ is the actual knife's edge: the capacity to represent a perfect solution is there (one seed above reaches exactly 100%), but whether training finds it depends on which seed it starts from (a preview of Lesson 33's optimization landscape problems).
By $H=4$, every seed reaches 100% reliably: there's enough capacity that the network stops being the bottleneck, and training reliably finds a solution within that capacity. This is the general shape of a capacity curve — a hard floor set by what the model can represent, with optimization difficulty riding on top of it near the floor's edge. This same curve is revisited in Lesson 35 from the opposite direction: there, capacity is held generously high and data is scarce, which turns "enough capacity to represent the right answer" into "also enough capacity to memorize the wrong one."
Width isn't the only knob. Depth — stacking more layers instead of making a layer wider — is the other axis, and it isn't just "width in disguise": a deep, narrow network can represent some functions far more compactly than a shallow, wide one needs to (fewer total units for the same expressiveness), but it introduces its own failure mode instead. Lesson 37 picks this up directly: stacking enough layers can make gradients vanish before they ever reach the earliest ones, a problem not encountered by this lesson's shallow 2-layer network.
Exercises
- The capacity sweep above used ReLU. Rerun it with
tanhinstead (swapforward/backward's activation and its derivative throughouttrain_and_eval, mirroring Exercise 2 below). Does the same $H=1$ ceiling and $H=3$-to-$H=4$ transition appear, or does a smooth activation change where the floor sits? - Replace
relu/relu_derivwithtanh/its derivative ($1 - \tanh^2$) throughout, and retrain. Does it still solve the problem? Compare the resulting loss curve's shape to the ReLU version's. - Remove the nonlinearity entirely (replace
relu(z1)with justz1inforward, andrelu_deriv(z1)with an array of ones inbackward). Confirm the network can no longer beat Lesson 31's ~50% ceiling — consistent with the collapse-to-a-single-projection argument above, now demonstrated on the actual training dynamics instead of just the static algebra.